오일러의 정리: 남길 수를 직접 세면 지수가 정해집니다
《나머지에서 시작하는 정수론》 · 5/8편 · 오일러의 정리
0. 서론: 합성수에서는 어느 나머지를 남길까요
페르마의 소정리에서는 소수 $p$로 나눈 0이 아닌 나머지 전체를 목록으로 사용했습니다.
각각에 $p$의 배수가 아닌 수를 곱하면 목록이 재배열되었고, 전체 곱을 비교하여 $a^{p-1}\equiv1\pmod p$를 얻었습니다.
법이 12라면 어떻게 될까요? 0이 아니라고 모두 역원을 갖는 것은 아닙니다. 2는 12와 공통인수 2를 갖고, 3은 공통인수 3을 가집니다. 반면 1·5·7·11은 12와 서로소여서 역원이 있습니다.
그렇다면 역원이 있는 1·5·7·11만 남기고 앞 편처럼 곱해보면 어떨까요?
우리가 계속 알아내려는 것은 “같은 수를 몇 번 곱하면 나머지가 1이 되는가”입니다.
앞 편에서는 목록의 각 수에 같은 수를 한 번씩 곱했지요. 그래서 목록이 몇 칸인지 알면, 전체 곱에 그 수가 몇 번 들어가는지도 알 수 있었습니다.
이번에도 같은 길로 가보겠습니다. 먼저 12와 서로소인 수가 몇 개인지 세고, 그 수들에 곱셈을 해도 목록이 유지되는지 확인하겠습니다.
세어서 얻은 개수가 거듭제곱의 지수로 바뀌는 과정을 따라가보는 것입니다.
이번 편의 오일러 정리(Euler's theorem)는 바로 이 나머지에 관한 정리입니다. 복소수에서 등장하는 $e^{i\theta}$의 오일러 공식과는 다른 내용입니다. 여기서는 정수와 최대공약수만 사용합니다.
1. 피( $\varphi$, phi ) 함수는 서로소인 수의 개수입니다
12를 예로 1부터 12까지 적어봅시다. 하나씩 최대공약수를 구해도 되지만, 이번에는 12와 공통인수를 가진 수를 지우는 방식으로 세어보겠습니다. 짝수와 3의 배수를 지우면 다음 네 수가 남습니다.
이 네 수는 12와 공통된 양의 약수가 1뿐입니다.
지금 필요한 답은 네 수의 합이나 곱이 아니라, 목록에 자리가 네 개 있다는 사실입니다.
법이 달라질 때도 이 개수를 계속 사용할 테니, 개수를 나타내는 기호를 하나 붙여두겠습니다.
양의 정수 $n$에 대해 1부터 $n$까지 중 $n$과 서로소인 수의 개수를 $\varphi(n)$이라고 씁니다.
$\varphi$는 그리스 문자 피(phi)이며 이 문자를 쓴, 위의 규칙에 해당하는 함수를 오일러 피 함수라고 부릅니다.
$n>1$이면 $n$ 자기자신은 서로소가 아니므로 1부터 $n$까지가 아닌, 1부터 $n-1$까지 세어도 같습니다.
기호 $\#$는 뒤에 있는 집합의 원소 개수라는 뜻입니다. 집합 표기가 낯설다면 “조건을 만족하는 정수 $r$의 개수”라고 읽으면 됩니다. 따라서
$$ \varphi(n)=n ( \{r|1\le r\le n,\ \gcd(r,n)=1\} ). $$
한국에서는 이쪽이 더 익숙한 표기일 겁니다. 집합의 원소 개수는 $n(A)$로, 조건은 $|$로 나타내는 것이 학교 수학에서 흔하기 때문입니다.
국제적으로는 집합의 원소 개수를 $\#A$ 또는 $|A|$로 나타내기도 하며, 조건을 구분하는 기호로는 $:$과 $|$를 모두 사용합니다. 참고로 $|A|$는 절댓값과 같은 모양의 기호지만, 집합에 사용하면 그 집합의 원소 개수를 뜻합니다.
여기서 한 가지 짚고 갈까요? $n(A)$에서 앞의 글자는 ‘집합의 원소 개수를 센다’는 표기입니다. 지금 기준으로 삼은 정수 $n$을 집합에 곱하라는 뜻은 아닙니다. 같은 글자가 두 역할로 쓰이므로 헷갈린다면, 위의 $\#$ 표기로 읽으셔도 됩니다.
위의 수식을 다시 한 번 짧게 정리하면 다음과 같습니다.
소수 $p$에서는 1부터 $p-1$까지가 모두 $p$와 서로소이므로 $\varphi(p)=p-1$입니다. 앞 편의 지수 $p-1$을 “법과 서로소인 나머지의 개수”로 다시 읽을 수 있습니다. 합성수에서도 이 개수를 사용하면 일반화할 길이 열립니다.
2. 12에서 지우고, 겹친 부분을 되돌려놓기
12의 소인수는 2와 3입니다. 소인수는 어떤 수를 나누는 소수입니다. 12와 1보다 큰 공통인수가 있다는 말은 2 또는 3을 인수로 갖는다는 말과 같습니다. 따라서 서로소인 수를 세려면 2의 배수와 3의 배수를 지우면 됩니다.
일반적으로 $d$가 $n$의 약수이면, 1부터 $n$까지의 $d$의 배수는 $d,2d,\ldots,(n/d)d$입니다. 따라서 정확히 $n/d$개입니다. 아래에서 쓰는 분수는 대략적인 비율이 아니라 이 정확한 개수를 나타냅니다.
1부터 12까지에서 2의 배수는 2·4·6·8·10·12로 6개입니다. 3의 배수는 3·6·9·12로 4개입니다. 12개에서 6개와 4개를 빼면 2개가 남을 것 같지만 실제 정답은 4개였습니다.
이유는 6과 12를 두 번 지웠기 때문입니다. 둘 다 2와 3의 배수입니다. 중복해서 뺀 2개를 한 번 되돌려놓으면
방금 센 6개·4개·2개가 각각 어디서 왔는지 드러내려고, 12를 해당 배수의 간격으로 나눈 몫으로 적어보겠습니다. 이렇게 적으면 12 이외의 수에서도 쓸 수 있는 모양이 됩니다.
괄호 안의 네 항은 차례대로 전체, 3의 배수 제외, 2의 배수 제외, 두 조건의 겹침 복구에 대응합니다. 여기서 두 괄호의 곱은 어떻게 나올까요? 다음처럼 전개하면 방금 센 네 항이 그대로 나옵니다.
따라서 앞의 값은 $12(1-1/2)(1-1/3)$으로도 쓸 수 있습니다. 직접 센 식을 이렇게 곱으로 묶어두면, 소인수가 늘어날 때에도 같은 계산을 이어갈 수 있습니다.
이런 식으로 전체에서 제외할 집합을 빼고, 겹쳐 빠진 부분을 되돌리는 방법을 포함배제라고 부릅니다. 이름을 외우기보다 6과 12가 두 번 지워졌다는 장면을 기억하면 충분합니다.
“되돌려놓는다”는 말이 6과 12를 최종 답에 포함한다는 뜻은 아닙니다. 두 수는 전체 12개 속에서 처음 한 번씩 세어졌습니다. 2의 배수라는 이유로 한 번, 3의 배수라는 이유로 또 한 번 빼면 등장 횟수가 $1-1-1=-1$이 됩니다. 한 번 더해 $1-1-1+1=0$으로 맞추어야 실제로 제외된 상태가 됩니다.
2의 배수에만 속하는 4는 $1-1=0$, 3의 배수에만 속하는 9도 $1-1=0$입니다. 어느 쪽에도 속하지 않는 5는 빼는 단계가 없어서 1로 남습니다. 포함배제는 이처럼 원하지 않는 수의 최종 횟수를 0, 원하는 수의 최종 횟수를 1로 맞추는 세기입니다.
분수 $1-\frac12$는 절반을 지운 뒤 남은 비율로 읽을 수 있습니다. 여러 비율을 곱할 수 있다는 근거는 방금의 포함배제 계산입니다. 이제 제외할 소수가 세 종류인 30에서도 그 근거를 확인해보겠습니다.
3. 30에서는 겹침이 세 겹까지 생깁니다
30의 서로 다른 소인수는 2·3·5입니다. 따라서 1부터 30까지에서 이 세 소수 중 하나라도 나누는 수를 제외합니다.
먼저 2·3·5의 배수를 각각 빼면
입니다. 이번에는 두 집합의 겹침을 되돌립니다. 2와 3의 공배수는 6의 배수, 2와 5의 공배수는 10의 배수, 3과 5의 공배수는 15의 배수입니다. 각각 5개, 3개, 2개가 있습니다.
왜 2와 3의 공배수가 정확히 6의 배수일까요?
되게 뜬금없죠? 너무나도 당연하게 생각하던 거니까요? 그러나 지금까지 우리는 '양방향 증명'을 해왔기 때문에 여기서도 한 번 적용해 보겠습니다.
6의 배수이면 2와 3의 배수인 것은 바로 확인됩니다. (1)
반대로 $k=2t$이고 3도 $k$를 나눈다면 $3\mid2t$입니다. 2와 3이 서로소이므로 3편의 약분 성질에 따라 $3\mid t$이고(유클리드 보조정리죠? $2t$가 3의 배수라면, 3이라는 인수는 2가 아니라 $t$ 쪽에 있어야 하기 때문에 2를 지울 수 있죠),
$ t = 3u $라고 쓸 수 있습니다.
그렇다면 $k=2\times3u=6u$가 되고, 여기서 $k$는 6의 배수임을 알 수 있습니다. (2)
(1)과 (2)를 통해 양방향 증명이 끝났습니다.
여기서 끝내면 9가 되지만 정답은 8입니다. 세 조건에 모두 속한 30을 보겠습니다. 처음에는 한 번 세었고, 세 집합에서 세 번 빼고, 두 집합의 겹침에서 세 번 더했습니다. 최종 계수가 $1-3+3=1$이 되어 살아남았습니다. 실제로는 지워져야 하므로 세 겹의 겹침을 한 번 더 빼야 합니다.
여기서는 두 종류에만 속한 수와 세 종류 모두에 속한 수를 나누어 생각하면 좋습니다. 예를 들어 6은 2와 3의 배수이지만 5의 배수는 아닙니다. 따라서 $1-2+1=0$번으로 이미 정확히 빠집니다. 30은 세 쌍, 즉 (2,3), (2,5), (3,5)의 공배수여서 두 겹을 복구하는 단계에서 세 번 더해집니다. 이 추가 겹침 하나를 마지막에 다시 보정하는 것입니다.
남는 수를 직접 적으면
로 정확히 여덟 개입니다. 포함배제 계산과 목록이 일치합니다.
30의 마지막 등장 횟수는 $1-3+3-1=0$입니다. 그림에서 각 보정 뒤의 횟수를 따라가면, 두 겹을 되돌린 다음 세 겹을 다시 빼는 이유가 보입니다.
그림을 만든 Python 코드
from pathlib import Path as _bfPath
from matplotlib.font_manager import FontProperties as _bfFontProperties
from matplotlib.text import Text as _bfText
from matplotlib.ticker import Formatter as _bfFormatter
from io import BytesIO as _bfBytesIO
from IPython.display import display as _bfDisplay, Image as _bfImage

class _BilingualFormatter(_bfFormatter):
    def __init__(self, base, labels):
        self.base, self.labels = base, labels
    def set_axis(self, axis):
        super().set_axis(axis)
        self.base.set_axis(axis)
    def set_locs(self, locs):
        super().set_locs(locs)
        self.base.set_locs(locs)
    def __call__(self, value, pos=None):
        raw=self.base(value,pos)
        translated=self.labels.get(raw)
        return translated+'\n'+raw if translated else raw
    def get_offset(self):
        return self.base.get_offset()

def _apply_bilingual_figure(_bfFigure, _bfLabels, _bfOriginalPixels):
    if getattr(_bfFigure, '_bilingual_complete', False):
        return
    _bfFont = _bfPath('C:/Windows/Fonts/malgun.ttf')
    if not _bfFont.is_file():
        raise RuntimeError('Korean/English figures require the Malgun Gothic font.')
    _bfFamily = _bfFontProperties(fname=str(_bfFont)).get_name()
    # Keep the delivered original's aspect ratio.  A bilingual label must not
    # stretch the chart, its grid cells, cards or geometry vertically.
    _bfFigure.set_size_inches(_bfOriginalPixels[0] / 80,
                             _bfOriginalPixels[1] / 80, forward=True)
    _bfFigure._bilingual_original_pixels = tuple(_bfOriginalPixels)
    _bfFigure.canvas.draw()
    for _bfAxes in _bfFigure.axes:
        for _bfAxis in (_bfAxes.xaxis,_bfAxes.yaxis):
            if any(_bfTick.get_text() in _bfLabels for _bfTick in _bfAxis.get_majorticklabels()):
                _bfAxis.set_major_formatter(_BilingualFormatter(_bfAxis.get_major_formatter(),_bfLabels))
    _bfTexts = list(_bfFigure.findobj(_bfText))
    for _bfAxes in _bfFigure.axes:
        for _bfTable in _bfAxes.tables:
            _bfTexts.extend(_bfCell.get_text() for _bfCell in _bfTable.get_celld().values())
    _bfSeen = set()
    _bfChanged = []
    for _bfItem in _bfTexts:
        if id(_bfItem) in _bfSeen:
            continue
        _bfSeen.add(id(_bfItem))
        _bfOriginal = _bfItem.get_text()
        _bfKorean = _bfLabels.get(_bfOriginal)
        if _bfKorean:
            _bfItem.set_text(_bfKorean + '\n' + _bfOriginal)
            _bfItem.set_linespacing(1.05)
            _bfChanged.append((_bfKorean, _bfOriginal))
        _bfProperties = _bfItem.get_fontproperties().copy()
        _bfProperties.set_file(None)
        _bfProperties.set_family([_bfFamily, 'DejaVu Sans'])
        _bfItem.set_fontproperties(_bfProperties)
    assert _bfChanged, 'Every figure must contain meaningful Korean/English labels.'
    # Bilingual column headers must stay inside their original table cells.
    _bfFigure.canvas.draw()
    _bfRenderer = _bfFigure.canvas.get_renderer()
    for _bfAxes in _bfFigure.axes:
        for _bfTable in _bfAxes.tables:
            for _bfCell in _bfTable.get_celld().values():
                _bfCellText = _bfCell.get_text()
                _bfBox = _bfCellText.get_window_extent(_bfRenderer)
                _bfCellBox = _bfCell.get_window_extent(_bfRenderer)
                if _bfBox.width and _bfBox.height:
                    _bfFit = min(1, .92*_bfCellBox.width/_bfBox.width,
                                  .88*_bfCellBox.height/_bfBox.height)
                    _bfCellText.set_fontsize(_bfCellText.get_fontsize()*_bfFit)
        if _bfAxes.get_title():
            _bfAxes.set_title(_bfAxes.get_title(), pad=6)
    _bfFigure.canvas.draw()
    # Keep subplot headings clear of the shared two-line title, moving the
    # subplot boundary only as much as the actual rendered text requires.
    if _bfFigure._suptitle is not None:
        _bfTopTitle = _bfFigure._suptitle.get_window_extent(_bfRenderer)
        for _bfAxes in _bfFigure.axes:
            if not _bfAxes.get_title():
                continue
            _bfHeading = _bfAxes.title.get_window_extent(_bfRenderer)
            _bfGap = _bfHeading.y1 - (_bfTopTitle.y0 - 9)
            if _bfGap > 0:
                _bfPosition = _bfAxes.get_position(original=True)
                _bfAxes.set_position([_bfPosition.x0, _bfPosition.y0,
                    _bfPosition.width, _bfPosition.height - _bfGap/_bfFigure.bbox.height])
    _bfFigure._bilingual_labels = _bfChanged
    _bfFigure._bilingual_complete = True

def _display_bilingual_figure(_bfFigure):
    # A fixed full canvas avoids notebook's automatic tight crop changing the
    # aspect ratio after titles and labels become bilingual.  This is a fresh
    # Matplotlib rendering, at exactly twice the original pixel dimensions.
    global _bfDisplayedFigure
    _bfDisplayedFigure = _bfFigure
    _bfBuffer = _bfBytesIO()
    _bfFigure.savefig(_bfBuffer, format='png', dpi=160, bbox_inches=None,
                      pad_inches=0, facecolor=_bfFigure.get_facecolor())
    _bfDisplay(_bfImage(data=_bfBuffer.getvalue()))
    plt.close(_bfFigure)

_bfLabels = {'Dividend': '피제수', 'Divisor': '제수', 'Quotient': '몫', 'Remainder': '나머지', '3r mod 7': '3r의 법 7 나머지', 'then x5': '그다음 5를 곱하기', 'k, gcd(k,12)=1': '12와 서로소인 k', '5k mod 12': '5k의 법 12 나머지', 'Modulus': '법', 'Other factors': '나머지 법들의 곱', 'Inverse': '역원', 'Unit part': '단위 부품', 'Target': '목표 나머지', 'Contribution': '기여값', 'Possible square residues': '가능한 제곱 나머지', 'Squares of 0, 1, ... , m-1': '0·1·…·(m−1)의 제곱 나머지', 'PASS': '통과', 'IMPOSSIBLE': '불가능', 'mod 2': '법 2', 'mod 3': '법 3', 'mod 4': '법 4', 'mod 5': '법 5', 'mod 7': '법 7', 'mod 8': '법 8', 'mod 9': '법 9', 'mod 11': '법 11', 'mod 12': '법 12', 'mod 105': '법 105', 'No excluded prime: 8 numbers': '세 소인수의 배수 아님: 8개', 'Exactly one: 14 numbers': '정확히 한 조건: 14개', 'Exactly two: 7 numbers': '정확히 두 조건: 7개', 'All three: 1 numbers': '세 조건 모두: 1개', 'Membership among the 2, 3, 5 multiples': '2·3·5의 배수 집합에 속하는 방식', 'total 30': '누적 30', 'total -1': '누적 −1', 'total 9': '누적 9', 'total 8': '누적 8', 'Running count': '누적 개수', 'Inclusion-exclusion corrects how often each number was counted': '포함배제로 각 수가 세어진 횟수를 바로잡는다', 'A number in all three sets has coefficient 1 - 3 + 3 - 1 = 0; an unexcluded number keeps coefficient 1.': '세 집합 모두에 속하면 계수는 1 − 3 + 3 − 1 = 0, 제외되지 않으면 1이다.'}
_bfOriginalPixels = [1280, 717]

from math import gcd, isqrt
import numpy as np
import matplotlib.pyplot as plt
from matplotlib.colors import ListedColormap
from matplotlib.patches import Rectangle, Circle, FancyBboxPatch, FancyArrowPatch

BG = "#101827"
PANEL = "#1d2b40"
INK = "#edf3fc"
MUTED = "#c0cede"
BLUE = "#8fdcff"
GREEN = "#91e0b2"
GOLD = "#ffd18c"
RED = "#ffaaaa"
LINE = "#667a96"

def canvas(rows=1, cols=1, size=(13.6, 6.8), title=""):
    fig, axes = plt.subplots(rows, cols, figsize=size, facecolor=BG,
                             squeeze=False)
    axes = axes.ravel().tolist()
    for ax in axes:
        ax.set_facecolor(BG)
        ax.tick_params(colors=INK, labelsize=12)
        for spine in ax.spines.values():
            spine.set_color(LINE)
    fig.suptitle(title, fontsize=18, color=INK, y=.98)
    fig.subplots_adjust(left=.07, right=.97, top=.86, bottom=.13,
                        wspace=.34, hspace=.48)
    return fig, axes

def off(ax):
    ax.set_xlim(0, 1)
    ax.set_ylim(0, 1)
    ax.axis("off")

def text(ax, x, y, value, color=INK, size=12, **kwargs):
    defaults = dict(ha="center", va="center", fontsize=size, color=color,
                    transform=ax.transAxes, linespacing=1.35)
    defaults.update(kwargs)
    return ax.text(x, y, value, **defaults)

def card(ax, x, y, width, height, value, edge=LINE, color=INK, size=14):
    ax.add_patch(FancyBboxPatch((x, y), width, height,
                 boxstyle="round,pad=0.012", transform=ax.transAxes,
                 facecolor=PANEL, edgecolor=edge, linewidth=1.4))
    text(ax, x+width/2, y+height/2, value, color=color, size=size)

def arrow(ax, start, end, color=BLUE):
    ax.add_patch(FancyArrowPatch(start, end, transform=ax.transAxes,
                 arrowstyle="-|>", mutation_scale=18,
                 color=color, linewidth=1.7))

def caption(fig, value):
    fig.text(.5, .035, value, ha="center", va="center",
             color=MUTED, fontsize=12)

fig,axes=canvas(1,2,size=(14,7.3),title="Inclusion-exclusion corrects how often each number was counted")
ax=axes[0]
off(ax)
labels=["No excluded prime","Exactly one","Exactly two","All three"]
groups=[[k for k in range(1,31) if sum(k%p==0 for p in (2,3,5))==r] for r in range(4)]
for row,(label,group) in enumerate(zip(labels,groups)):
    y=.77-row*.19
    card(ax,.01,y,.98,.14,f"{label}: {len(group)} numbers",edge=GREEN if row==0 else LINE,size=14)
text(ax,.5,.96,"Membership among the 2, 3, 5 multiples",color=BLUE,size=14)
ax=axes[1]
entries=[("Start",30),("Subtract singles",-31),("Add pairs",10),("Subtract triple",-1)]
running=0
for j,(label,change) in enumerate(entries):
    new=running+change
    ax.bar(j,abs(change),bottom=min(running,new),width=.58,
           color=GREEN if change>0 else RED,edgecolor=LINE)
    ax.text(j,max(running,new)+1.2,f"{change:+d}",ha="center",color=INK,fontsize=13)
    ax.text(j,new-1.2 if change<0 else new+4,f"total {new}",ha="center",
            va="top" if change<0 else "bottom",color=GOLD,fontsize=12)
    running=new
ax.axhline(0,color=LINE,linewidth=1)
ax.set_xticks(range(4),["30","15 + 10 + 6","5 + 3 + 2","1"])
ax.set_ylim(-8,42)
ax.set_ylabel("Running count",color=INK,fontsize=12)
ax.set_title("30 - 31 + 10 - 1 = 8",color=INK,fontsize=16,pad=15)
caption(fig,"A number in all three sets has coefficient 1 - 3 + 3 - 1 = 0; an unexcluded number keeps coefficient 1.")
assert [len(g) for g in groups]==[8,14,7,1]
assert 30-(15+10+6)+(5+3+2)-1==8 and running==8
_apply_bilingual_figure(plt.gcf(), _bfLabels, _bfOriginalPixels)
_display_bilingual_figure(plt.gcf())
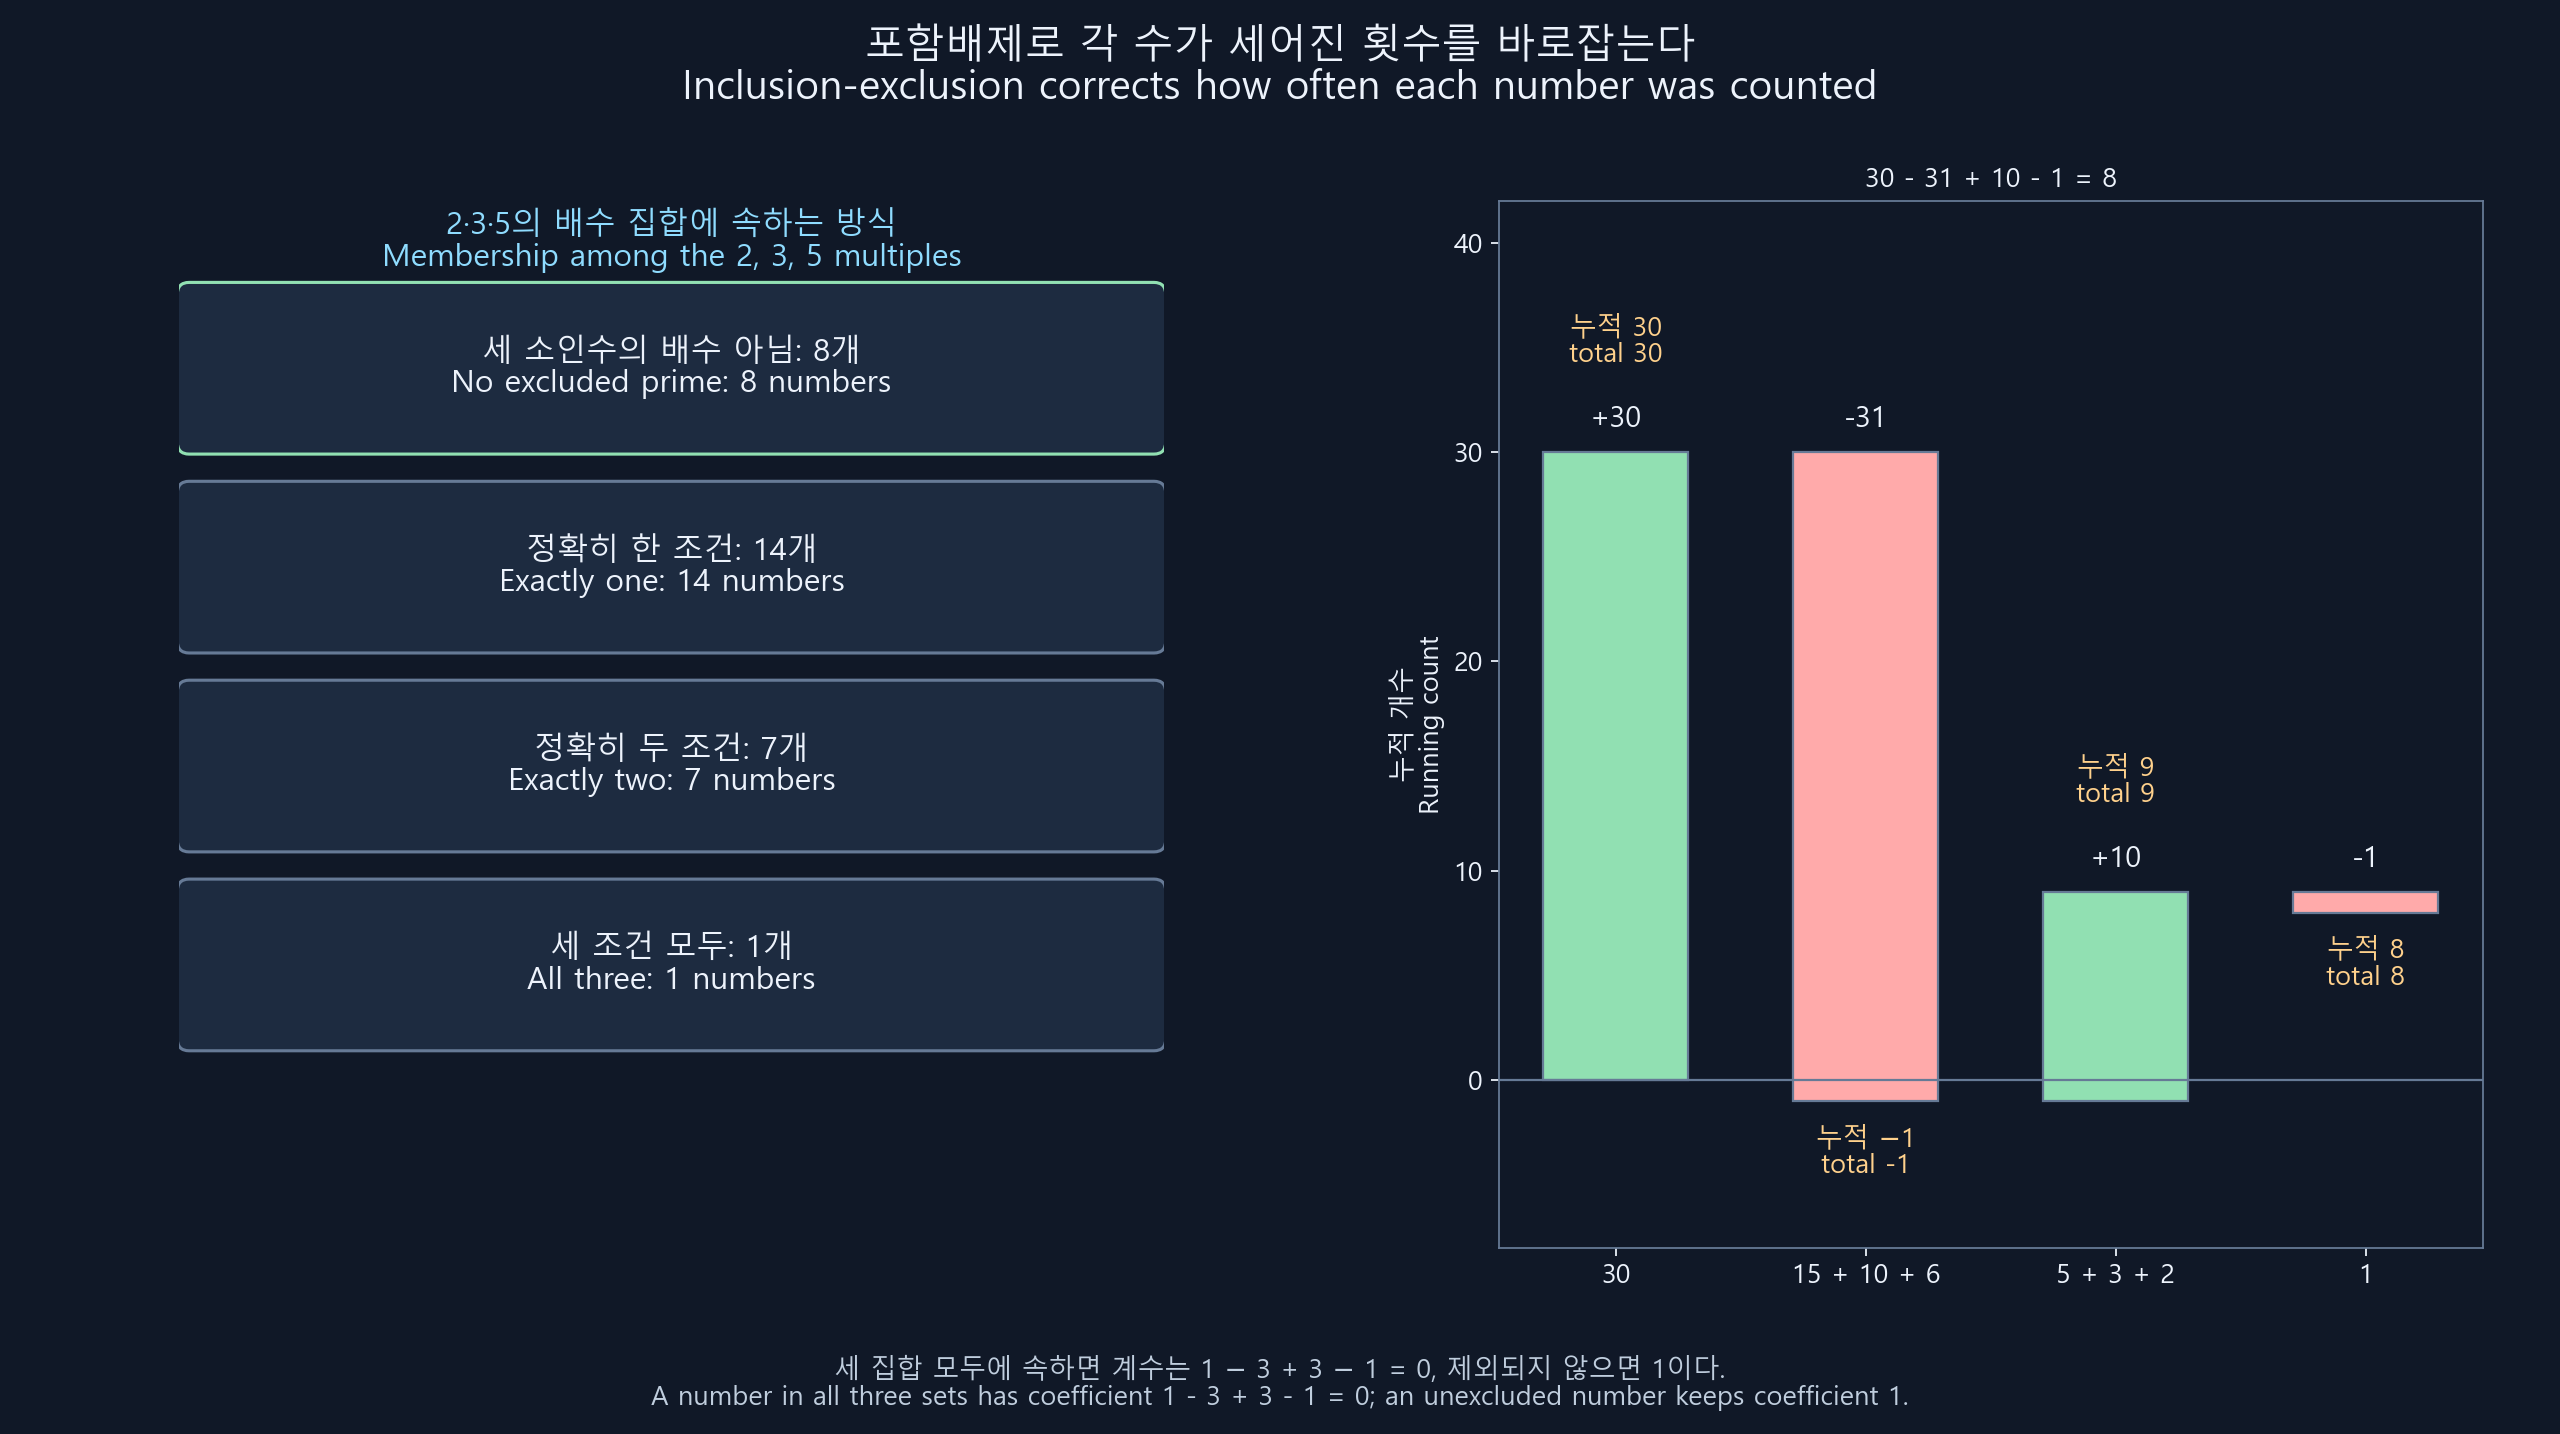
앞에서는 실제로 지운 개수를 계산했습니다. 이제 그 계산을 짧은 곱으로 묶어두겠습니다. 각 항에서 30을 밖으로 꺼내면, 괄호 안에는 어느 소수의 배수를 빼고 어느 겹침을 복구했는지가 분수로 남습니다.
곱을 전개하면 단일 제외, 두 겹의 복구, 세 겹의 제외가 정확히 나타납니다. 수가 더 많아져도 같은 방식으로 일반화할 수 있습니다.
그림을 만든 Python 코드
from pathlib import Path as _bfPath
from matplotlib.font_manager import FontProperties as _bfFontProperties
from matplotlib.text import Text as _bfText
from matplotlib.ticker import Formatter as _bfFormatter
from io import BytesIO as _bfBytesIO
from IPython.display import display as _bfDisplay, Image as _bfImage

class _BilingualFormatter(_bfFormatter):
    def __init__(self, base, labels):
        self.base, self.labels = base, labels
    def set_axis(self, axis):
        super().set_axis(axis)
        self.base.set_axis(axis)
    def set_locs(self, locs):
        super().set_locs(locs)
        self.base.set_locs(locs)
    def __call__(self, value, pos=None):
        raw=self.base(value,pos)
        translated=self.labels.get(raw)
        return translated+'\n'+raw if translated else raw
    def get_offset(self):
        return self.base.get_offset()

def _apply_bilingual_figure(_bfFigure, _bfLabels, _bfOriginalPixels):
    if getattr(_bfFigure, '_bilingual_complete', False):
        return
    _bfFont = _bfPath('C:/Windows/Fonts/malgun.ttf')
    if not _bfFont.is_file():
        raise RuntimeError('Korean/English figures require the Malgun Gothic font.')
    _bfFamily = _bfFontProperties(fname=str(_bfFont)).get_name()
    # Keep the delivered original's aspect ratio.  A bilingual label must not
    # stretch the chart, its grid cells, cards or geometry vertically.
    _bfFigure.set_size_inches(_bfOriginalPixels[0] / 80,
                             _bfOriginalPixels[1] / 80, forward=True)
    _bfFigure._bilingual_original_pixels = tuple(_bfOriginalPixels)
    _bfFigure.canvas.draw()
    for _bfAxes in _bfFigure.axes:
        for _bfAxis in (_bfAxes.xaxis,_bfAxes.yaxis):
            if any(_bfTick.get_text() in _bfLabels for _bfTick in _bfAxis.get_majorticklabels()):
                _bfAxis.set_major_formatter(_BilingualFormatter(_bfAxis.get_major_formatter(),_bfLabels))
    _bfTexts = list(_bfFigure.findobj(_bfText))
    for _bfAxes in _bfFigure.axes:
        for _bfTable in _bfAxes.tables:
            _bfTexts.extend(_bfCell.get_text() for _bfCell in _bfTable.get_celld().values())
    _bfSeen = set()
    _bfChanged = []
    for _bfItem in _bfTexts:
        if id(_bfItem) in _bfSeen:
            continue
        _bfSeen.add(id(_bfItem))
        _bfOriginal = _bfItem.get_text()
        _bfKorean = _bfLabels.get(_bfOriginal)
        if _bfKorean:
            _bfItem.set_text(_bfKorean + '\n' + _bfOriginal)
            _bfItem.set_linespacing(1.05)
            _bfChanged.append((_bfKorean, _bfOriginal))
        _bfProperties = _bfItem.get_fontproperties().copy()
        _bfProperties.set_file(None)
        _bfProperties.set_family([_bfFamily, 'DejaVu Sans'])
        _bfItem.set_fontproperties(_bfProperties)
    assert _bfChanged, 'Every figure must contain meaningful Korean/English labels.'
    # Bilingual column headers must stay inside their original table cells.
    _bfFigure.canvas.draw()
    _bfRenderer = _bfFigure.canvas.get_renderer()
    for _bfAxes in _bfFigure.axes:
        for _bfTable in _bfAxes.tables:
            for _bfCell in _bfTable.get_celld().values():
                _bfCellText = _bfCell.get_text()
                _bfBox = _bfCellText.get_window_extent(_bfRenderer)
                _bfCellBox = _bfCell.get_window_extent(_bfRenderer)
                if _bfBox.width and _bfBox.height:
                    _bfFit = min(1, .92*_bfCellBox.width/_bfBox.width,
                                  .88*_bfCellBox.height/_bfBox.height)
                    _bfCellText.set_fontsize(_bfCellText.get_fontsize()*_bfFit)
        if _bfAxes.get_title():
            _bfAxes.set_title(_bfAxes.get_title(), pad=6)
    _bfFigure.canvas.draw()
    # Keep subplot headings clear of the shared two-line title, moving the
    # subplot boundary only as much as the actual rendered text requires.
    if _bfFigure._suptitle is not None:
        _bfTopTitle = _bfFigure._suptitle.get_window_extent(_bfRenderer)
        for _bfAxes in _bfFigure.axes:
            if not _bfAxes.get_title():
                continue
            _bfHeading = _bfAxes.title.get_window_extent(_bfRenderer)
            _bfGap = _bfHeading.y1 - (_bfTopTitle.y0 - 9)
            if _bfGap > 0:
                _bfPosition = _bfAxes.get_position(original=True)
                _bfAxes.set_position([_bfPosition.x0, _bfPosition.y0,
                    _bfPosition.width, _bfPosition.height - _bfGap/_bfFigure.bbox.height])
    _bfFigure._bilingual_labels = _bfChanged
    _bfFigure._bilingual_complete = True

def _display_bilingual_figure(_bfFigure):
    # A fixed full canvas avoids notebook's automatic tight crop changing the
    # aspect ratio after titles and labels become bilingual.  This is a fresh
    # Matplotlib rendering, at exactly twice the original pixel dimensions.
    global _bfDisplayedFigure
    _bfDisplayedFigure = _bfFigure
    _bfBuffer = _bfBytesIO()
    _bfFigure.savefig(_bfBuffer, format='png', dpi=160, bbox_inches=None,
                      pad_inches=0, facecolor=_bfFigure.get_facecolor())
    _bfDisplay(_bfImage(data=_bfBuffer.getvalue()))
    plt.close(_bfFigure)

_bfLabels = {'Dividend': '피제수', 'Divisor': '제수', 'Quotient': '몫', 'Remainder': '나머지', '3r mod 7': '3r의 법 7 나머지', 'then x5': '그다음 5를 곱하기', 'k, gcd(k,12)=1': '12와 서로소인 k', '5k mod 12': '5k의 법 12 나머지', 'Modulus': '법', 'Other factors': '나머지 법들의 곱', 'Inverse': '역원', 'Unit part': '단위 부품', 'Target': '목표 나머지', 'Contribution': '기여값', 'Possible square residues': '가능한 제곱 나머지', 'Squares of 0, 1, ... , m-1': '0·1·…·(m−1)의 제곱 나머지', 'PASS': '통과', 'IMPOSSIBLE': '불가능', 'mod 2': '법 2', 'mod 3': '법 3', 'mod 4': '법 4', 'mod 5': '법 5', 'mod 7': '법 7', 'mod 8': '법 8', 'mod 9': '법 9', 'mod 11': '법 11', 'mod 12': '법 12', 'mod 105': '법 105', 'Count numbers coprime to 30 by excluding multiples of 2, 3, and 5': '2·3·5의 배수를 제외하며 30과 서로소인 수를 센다'}
_bfOriginalPixels = [1123, 546]

from math import gcd
import matplotlib.pyplot as plt
from matplotlib.patches import Rectangle

n=30; primes=[2,3,5]; units=[k for k in range(1,n+1) if gcd(k,n)==1]
assert units==[1,7,11,13,17,19,23,29]
fig,ax=plt.subplots(figsize=(11.5,5.6),facecolor="#0d1117"); ax.axis("off")
ax.set(xlim=(-.7,9.7),ylim=(-1,3.5))
for k in range(1,n+1):
    x=(k-1)%10; y=2-(k-1)//10
    ax.add_patch(Rectangle((x-.42,y-.33),.84,.66,facecolor="#216052" if k in units else "#252f40",edgecolor="#526276"))
    ax.text(x,y,str(k),ha="center",va="center",color="#91e0b2" if k in units else "#95a2b5",fontsize=18)
ax.text(4.5,-.55,"30 - 15 - 10 - 6 + 5 + 3 + 2 - 1 = 8",ha="center",color="#ffcf85",fontsize=19)
fig.suptitle("Count numbers coprime to 30 by excluding multiples of 2, 3, and 5",color="#e6edf3",fontsize=16)
fig.subplots_adjust(left=.02,right=.98,top=.88,bottom=.04)
_apply_bilingual_figure(plt.gcf(), _bfLabels, _bfOriginalPixels)
_display_bilingual_figure(plt.gcf())
print("Survivors:",units)
print("30 x (1 - 1/2) x (1 - 1/3) x (1 - 1/5) = 8")
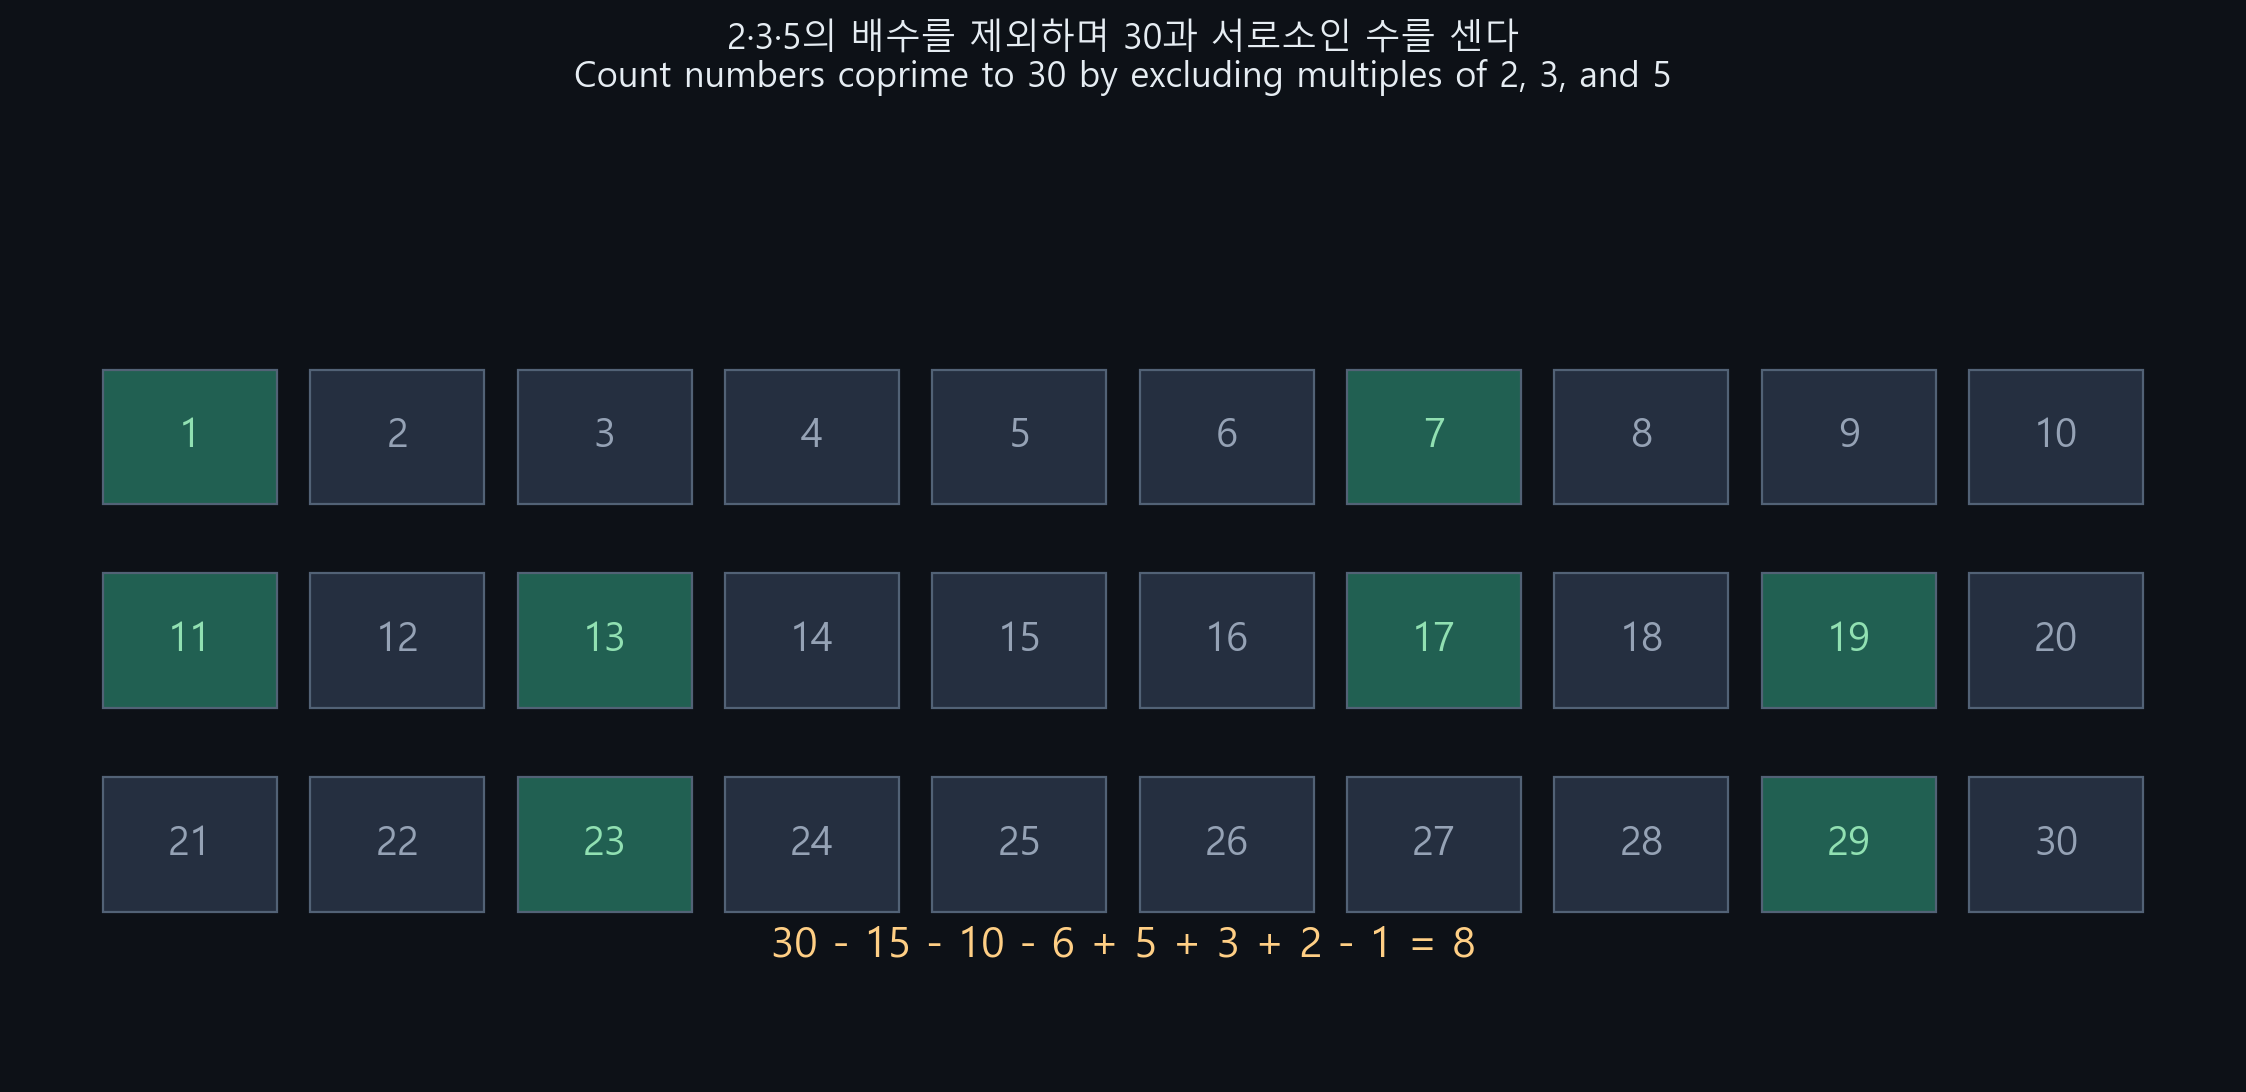
Survivors: [1, 7, 11, 13, 17, 19, 23, 29]
30 x (1 - 1/2) x (1 - 1/3) x (1 - 1/5) = 8
“각 소수의 배수가 아닐 비율을 곱하면 되겠다”는 직관은 이 범위에서는 맞습니다. 예를 들어 1부터 30까지에서 2의 배수인 비율은 $15/30=1/2$, 3의 배수인 비율은 $10/30=1/3$, 두 조건을 함께 만족하는 비율은 $5/30=1/6=(1/2)(1/3)$입니다. 서로 다른 소수들의 곱이 30을 나누므로 교집합도 정확한 몫으로 셀 수 있습니다. 위의 포함배제는 이 겹침들을 모두 계산해, 배수가 아닐 비율의 곱까지 정당화한 것입니다.
4. 소인수가 반복되어도 한 번만 지우는 이유
36은 $2^2\times3^2$입니다. 2와 3이 각각 두 번 들어 있지만, 36과 서로소인지를 검사할 때에는 2의 배수와 3의 배수를 한 번씩만 제외하면 됩니다. 4의 배수는 이미 2의 배수에 들어 있고, 9의 배수는 이미 3의 배수에 들어 있기 때문입니다.
따라서
실제 목록도 확인할 수 있습니다.
25는 합성수지만 36과 서로소여서 남습니다. “소수만 남긴다”가 아니라 “법과 공통 소인수가 없는 수를 남긴다”는 점을 구분해야 합니다.
$n=1$에서는 1 하나가 1과 서로소이므로 $\varphi(1)=1$입니다. 곱 공식에서도 곱할 항이 하나도 없을 때의 곱을 1로 정하면 같은 값이 나옵니다. 이제 $n>1$에서 소인수들을 이용해 세어보겠습니다.
12·30·36을 셀 때 달라진 것은 전체 범위와 지워야 할 소수의 목록이었습니다. 그 두 가지에 이름을 붙이면 같은 계산을 한 번에 적을 수 있겠지요. 일반적으로 $n$의 서로 다른 소인수를 $p_1,\ldots,p_s$라고 합시다. $s$는 서로 다른 소인수의 개수입니다. 이 중 $j$개의 소수를 골랐을 때, $i_1,\ldots,i_j$는 고른 소수들의 번호를 나타냅니다. 서로소가 아닌 수는 이 중 하나 이상의 배수입니다. $p_i$의 배수는 정확히 $n/p_i$개이고, 서로 다른 몇 소수의 배수를 동시에 만족하는 수는 그 곱의 배수이므로 $n/(p_{i_1}\cdots p_{i_j})$개입니다. 이 곱은 $n$의 약수라서 개수가 정수로 떨어집니다.
포함배제는 이 개수들을 한 개짜리는 빼고, 두 개짜리는 더하고, 세 개짜리는 빼는 방식으로 정리합니다. 30에서 소수 하나의 배수는 뺐고, 두 소수의 공배수는 더했으며, 세 소수의 공배수는 다시 뺐던 바로 그 계산입니다. 다음 식은 그 길어진 덧셈과 뺄셈을 곱 하나로 묶어놓은 것입니다. 괄호를 풀면 앞에서 세었던 항들이 다시 나타납니다.
$\prod$는 여러 항을 모두 곱한다는 기호이고, 아래의 $p\mid n$은 $n$을 나누는 서로 다른 소수 $p$를 한 번씩 사용한다는 뜻입니다. 예를 들어 36에서는 $p=2,3$만 넣습니다.
일반적인 곱에도 같은 장부가 들어 있습니다. 예를 들어 서로 다른 소인수가 네 개라면 전개에서 음수 항 하나를 고른 항은 단일 배수의 제외, 음수 항 두 개를 고른 항은 두 겹의 복구를 나타냅니다. 선택한 소수가 $j$개이면 부호는 $(-1)^j$이고, 분모는 선택한 소수들의 곱입니다. 그 곱은 $n$의 약수이므로 $n$을 곱했을 때 정확한 정수 개수가 됩니다.
소인수가 네 개 이상이어도 정말 같은 규칙이 될까요? 모든 겹침을 길게 나열하는 대신, 수 하나를 골라 최종적으로 몇 번 세어지는지 살펴보겠습니다. 남겨야 할 수는 한 번, 지워야 할 수는 0번 세어짐을 보이면 전체 개수도 맞습니다.
1부터 $n$까지의 정수 $k$를 하나 고릅니다. $k$가 검사하는 소수 어느 것의 배수도 아니라면, 전체를 셀 때 1회만 남고 어떤 제외 항에도 들어가지 않습니다.
반면 $k$가 적어도 하나의 검사하는 소수의 배수라면, 그 소수 하나를 $p$라고 정합니다.
이 수는 최종 목록에서 사라져야 합니다. 그러려면 이 수를 더하는 횟수와 빼는 횟수가 같다는 것을 보이면 되겠지요.
포함배제의 항들 가운데 $k$를 세는 항을 둘씩 짝지어보겠습니다.
30을 셀 때를 떠올려봅시다. 30은 전체를 셀 때 한 번 들어가고, 2의 배수를 뺄 때 한 번 빠집니다. 또 3의 배수를 뺄 때 한 번 빠지고, 2와 3의 공배수를 더할 때 한 번 돌아옵니다. 이렇게 “2를 검사하는 조건이 붙었는가”만 다른 항끼리 짝지으면, 한 쪽의 더하기와 다른 쪽의 빼기가 없어집니다. 아래는 이 짝짓기가 어떤 수에서도 빠짐없이 된다는 확인입니다.
전체를 한 번 세는 맨 앞의 $n$항($ \varphi(n) $의 첫 항)도 여기에 포함합니다. 이것은 아무 소수도 고르지 않은 항입니다.
예를 들어 $n=30$, $k=2$, $p=2$라면, 전체에서 2를 한 번 세는 항($n$항)과 2의 배수라서 한 번 빼는 항이 한 쌍입니다.
조금 더 복잡한 경우도 살펴보겠습니다. 이번에는 $k=6$, $p=2$라고 해봅시다.
6은 2와 3의 배수이므로 여러 항에서 등장합니다. 전체를 세는 항에서는 한 번 더하고, 2의 배수를 세는 항에서는 한 번 뺍니다. 이 둘은 서로 상쇄됩니다.
그런데 3의 배수를 세는 항에서도 6을 한 번 빼고, 2와 3의 공배수를 세는 항에서는 다시 한 번 더합니다. 이 둘도 서로 상쇄됩니다.
$$ (+1-1)+(-1+1)=0 $$
여기서 두 쌍의 공통점을 살펴보겠습니다. 첫 번째는 전체 정수와 2의 배수, 두 번째는 3의 배수와 2와 3의 공배수입니다.
두 경우 모두 한쪽에 '2의 배수'라는 조건을 하나 추가하면 다른 쪽이 됩니다. 이때 6은 두 조건을 모두 만족하므로 어느 쪽에서도 빠지지 않습니다.
반면 조건이 하나 늘어나면 포함배제 원리에 따라 더하기와 빼기가 뒤바뀝니다. 따라서 두 항에서 6을 세는 횟수는 서로 상쇄됩니다.
이처럼 '2의 배수'라는 조건을 추가하거나 제거하면 두 항을 서로 연결할 수 있습니다. 조건을 추가했다가 다시 제거하면 원래 항으로 돌아오므로, 같은 항을 중복해서 짝짓거나 빠뜨릴 일도 없습니다.(조건의 추가와 제거로 1:1대응이 성립하기 때문이다~ 라고 생각하시면 편합니다)
2 대신 $k$를 나누는 다른 소수 $p$를 골라도 마찬가지입니다. 결국 $k$를 세는 모든 항은 짝을 이루어 상쇄되고, 최종적으로 $k$가 세어지는 횟수는 0이 됩니다.
이 짝짓기는 $k$를 나누는, 검사하는 소수의 개수와 무관합니다. 곱의 전개에서 각 괄호의 1 또는 $-1/p$를 고르는 일이 바로 소수 선택에 해당하므로, 앞의 곱 공식이 모든 소인수 개수에서 성립합니다.
소수 $p$와 양의 정수 $e$에 대하여, 소수의 거듭제곱 $p^e$에서는 제외할 종류가 $p$의 배수 하나뿐이므로
여기서도 지수 $e$만큼 같은 비율을 반복해 곱하지 않습니다. 2의 배수를 이미 지웠는데 또 2의 배수를 지울 이유가 없기 때문입니다.
예를 들어 $2^3=8$에서 제외할 수는 2·4·6·8로 4개입니다. $8-4=4$이고 실제 남는 수는 1·3·5·7입니다. $e=3$이라고 $8(1-1/2)^3=1$로 계산하면 같은 “짝수 제외”를 다른 조건인 것처럼 세 번 적용한 셈이어서 틀립니다. 반복된 소인수는 법의 크기에는 영향을 주지만, 제외할 종류를 늘리지는 않습니다.
균등하게 1부터 $n$까지 하나를 고른다면 $\varphi(n)/n$은 서로소일 확률이라고 해석할 수 있습니다. 하지만 공식의 증명은 앞에서 정수들을 세는 것으로 끝났습니다. 확률의 언어는 그 결과를 읽는 또 하나의 방식입니다.
5. 법 12의 네 나머지에 5를 곱해보기
이제 세기를 끝냈으니, 그 개수를 어떻게 거듭제곱의 지수로 바꿀지 살펴봅시다. 법 12에서 역원을 갖는 나머지는 1·5·7·11입니다. 이번에는 5를 거듭 곱하는 경우를 보려고, 이 네 수에 각각 5를 곱하겠습니다. 5도 12와 서로소이므로 나중에 역원을 사용할 수 있습니다. 표의 마지막 열이 원래 네 수를 그대로 담고 있는지 확인해보세요.
| 원래 나머지 | 5를 곱한 값 | 법 12의 나머지 |
|---|---|---|
| 1 | 5 | 5 |
| 5 | 25 | 1 |
| 7 | 35 | 11 |
| 11 | 55 | 7 |
출력은 5·1·11·7입니다. 법이 합성수여도 역원 있는 네 수만 놓고 12와 서로소인 5를 곱하니 같은 목록이 돌아왔습니다. 이 현상을 일반적인 법에서도 보이면, 앞 편처럼 전체 곱을 비교할 수 있습니다.
여기서 주의할 점이 있습니다. 우리는 여전히 0부터 11까지, 12개의 눈금을 가진 시계를 사용하고 있습니다. 다만 그중에서 12와 서로소인 1, 5, 7, 11만 골라 계산하는 것입니다.
그렇다면 왜 굳이 이 네 수만 골랐을까요?
5를 곱했을 때 눈금이 서로 겹치지 않는 성질은 사실 12개의 눈금 전체에서도 성립합니다. 하지만 잠시 뒤에는 목록의 수들을 모두 곱한 다음, 양변에서 그 곱을 약분해야 합니다.
합동식에서는 아무 수나 약분할 수 없습니다. 약분하려는 수가 법인 12와 서로소여야 합니다.
1, 5, 7, 11은 모두 12와 서로소이므로, 이들을 곱한 수도 12와 서로소입니다. 따라서 마지막 약분까지 문제없이 진행할 수 있습니다.
결국 이 네 수를 고른 이유는 5를 곱했을 때 목록이 재배열될 뿐 아니라, 마지막에 그 목록의 곱을 약분할 수도 있기 때문입니다.
그림을 만든 Python 코드
from pathlib import Path as _bfPath
from matplotlib.font_manager import FontProperties as _bfFontProperties
from matplotlib.text import Text as _bfText
from matplotlib.ticker import Formatter as _bfFormatter
from io import BytesIO as _bfBytesIO
from IPython.display import display as _bfDisplay, Image as _bfImage

class _BilingualFormatter(_bfFormatter):
    def __init__(self, base, labels):
        self.base, self.labels = base, labels
    def set_axis(self, axis):
        super().set_axis(axis)
        self.base.set_axis(axis)
    def set_locs(self, locs):
        super().set_locs(locs)
        self.base.set_locs(locs)
    def __call__(self, value, pos=None):
        raw=self.base(value,pos)
        translated=self.labels.get(raw)
        return translated+'\n'+raw if translated else raw
    def get_offset(self):
        return self.base.get_offset()

def _apply_bilingual_figure(_bfFigure, _bfLabels, _bfOriginalPixels):
    if getattr(_bfFigure, '_bilingual_complete', False):
        return
    _bfFont = _bfPath('C:/Windows/Fonts/malgun.ttf')
    if not _bfFont.is_file():
        raise RuntimeError('Korean/English figures require the Malgun Gothic font.')
    _bfFamily = _bfFontProperties(fname=str(_bfFont)).get_name()
    # Keep the delivered original's aspect ratio.  A bilingual label must not
    # stretch the chart, its grid cells, cards or geometry vertically.
    _bfFigure.set_size_inches(_bfOriginalPixels[0] / 80,
                             _bfOriginalPixels[1] / 80, forward=True)
    _bfFigure._bilingual_original_pixels = tuple(_bfOriginalPixels)
    _bfFigure.canvas.draw()
    for _bfAxes in _bfFigure.axes:
        for _bfAxis in (_bfAxes.xaxis,_bfAxes.yaxis):
            if any(_bfTick.get_text() in _bfLabels for _bfTick in _bfAxis.get_majorticklabels()):
                _bfAxis.set_major_formatter(_BilingualFormatter(_bfAxis.get_major_formatter(),_bfLabels))
    _bfTexts = list(_bfFigure.findobj(_bfText))
    for _bfAxes in _bfFigure.axes:
        for _bfTable in _bfAxes.tables:
            _bfTexts.extend(_bfCell.get_text() for _bfCell in _bfTable.get_celld().values())
    _bfSeen = set()
    _bfChanged = []
    for _bfItem in _bfTexts:
        if id(_bfItem) in _bfSeen:
            continue
        _bfSeen.add(id(_bfItem))
        _bfOriginal = _bfItem.get_text()
        _bfKorean = _bfLabels.get(_bfOriginal)
        if _bfKorean:
            _bfItem.set_text(_bfKorean + '\n' + _bfOriginal)
            _bfItem.set_linespacing(1.05)
            _bfChanged.append((_bfKorean, _bfOriginal))
        _bfProperties = _bfItem.get_fontproperties().copy()
        _bfProperties.set_file(None)
        _bfProperties.set_family([_bfFamily, 'DejaVu Sans'])
        _bfItem.set_fontproperties(_bfProperties)
    assert _bfChanged, 'Every figure must contain meaningful Korean/English labels.'
    # Bilingual column headers must stay inside their original table cells.
    _bfFigure.canvas.draw()
    _bfRenderer = _bfFigure.canvas.get_renderer()
    for _bfAxes in _bfFigure.axes:
        for _bfTable in _bfAxes.tables:
            for _bfCell in _bfTable.get_celld().values():
                _bfCellText = _bfCell.get_text()
                _bfBox = _bfCellText.get_window_extent(_bfRenderer)
                _bfCellBox = _bfCell.get_window_extent(_bfRenderer)
                if _bfBox.width and _bfBox.height:
                    _bfFit = min(1, .92*_bfCellBox.width/_bfBox.width,
                                  .88*_bfCellBox.height/_bfBox.height)
                    _bfCellText.set_fontsize(_bfCellText.get_fontsize()*_bfFit)
        if _bfAxes.get_title():
            _bfAxes.set_title(_bfAxes.get_title(), pad=6)
    _bfFigure.canvas.draw()
    # Keep subplot headings clear of the shared two-line title, moving the
    # subplot boundary only as much as the actual rendered text requires.
    if _bfFigure._suptitle is not None:
        _bfTopTitle = _bfFigure._suptitle.get_window_extent(_bfRenderer)
        for _bfAxes in _bfFigure.axes:
            if not _bfAxes.get_title():
                continue
            _bfHeading = _bfAxes.title.get_window_extent(_bfRenderer)
            _bfGap = _bfHeading.y1 - (_bfTopTitle.y0 - 9)
            if _bfGap > 0:
                _bfPosition = _bfAxes.get_position(original=True)
                _bfAxes.set_position([_bfPosition.x0, _bfPosition.y0,
                    _bfPosition.width, _bfPosition.height - _bfGap/_bfFigure.bbox.height])
    _bfFigure._bilingual_labels = _bfChanged
    _bfFigure._bilingual_complete = True

def _display_bilingual_figure(_bfFigure):
    # A fixed full canvas avoids notebook's automatic tight crop changing the
    # aspect ratio after titles and labels become bilingual.  This is a fresh
    # Matplotlib rendering, at exactly twice the original pixel dimensions.
    global _bfDisplayedFigure
    _bfDisplayedFigure = _bfFigure
    _bfBuffer = _bfBytesIO()
    _bfFigure.savefig(_bfBuffer, format='png', dpi=160, bbox_inches=None,
                      pad_inches=0, facecolor=_bfFigure.get_facecolor())
    _bfDisplay(_bfImage(data=_bfBuffer.getvalue()))
    plt.close(_bfFigure)

_bfLabels = {'Dividend': '피제수', 'Divisor': '제수', 'Quotient': '몫', 'Remainder': '나머지', '3r mod 7': '3r의 법 7 나머지', 'then x5': '그다음 5를 곱하기', 'k, gcd(k,12)=1': '12와 서로소인 k', '5k mod 12': '5k의 법 12 나머지', 'Modulus': '법', 'Other factors': '나머지 법들의 곱', 'Inverse': '역원', 'Unit part': '단위 부품', 'Target': '목표 나머지', 'Contribution': '기여값', 'Possible square residues': '가능한 제곱 나머지', 'Squares of 0, 1, ... , m-1': '0·1·…·(m−1)의 제곱 나머지', 'PASS': '통과', 'IMPOSSIBLE': '불가능', 'mod 2': '법 2', 'mod 3': '법 3', 'mod 4': '법 4', 'mod 5': '법 5', 'mod 7': '법 7', 'mod 8': '법 8', 'mod 9': '법 9', 'mod 11': '법 11', 'mod 12': '법 12', 'mod 105': '법 105', 'Units modulo 12': '법 12의 가역 나머지', '5^4 ≡ 1 (mod 12)': '법 12에서 5^4의 나머지는 1', '5^2 ≡ 1 (mod 12): period 2': '5^2 ≡ 1 (mod 12): 주기 2', 'Euler permutes only the invertible residues': '오일러는 가역 나머지만 재배열한다'}
_bfOriginalPixels = [1087, 515]

from math import gcd
import matplotlib.pyplot as plt

n=12; a=5; units=[k for k in range(1,n) if gcd(k,n)==1]
after=[a*k%n for k in units]
assert units==[1,5,7,11] and sorted(after)==units
fig,axes=plt.subplots(1,2,figsize=(11.6,5.5),facecolor="#0d1117")
for ax in axes: ax.axis("off")
table=axes[0].table(cellText=list(zip(units,after)),colLabels=["k, gcd(k,12)=1", "5k mod 12"],loc="center",cellLoc="center")
table.auto_set_font_size(False); table.set_fontsize(17); table.scale(1,2.4)
for (r,c),cell in table.get_celld().items():
    cell.set_facecolor("#173f50" if r==0 else "#1c2534"); cell.set_edgecolor("#526276"); cell.set_text_props(color="#e6edf3")
axes[1].text(.5,.78,"Units modulo 12",ha="center",color="#bdc7d5",fontsize=16)
axes[1].text(.5,.55,"1, 5, 7, 11",ha="center",color="#91e0b2",fontsize=25)
axes[1].text(.5,.28,"5^4 ≡ 1 (mod 12)",ha="center",color="#93e5ff",fontsize=22)
axes[1].text(.5,.06,"5^2 ≡ 1 (mod 12): period 2",ha="center",color="#ffcf85",fontsize=14)
fig.suptitle("Euler permutes only the invertible residues",color="#e6edf3",fontsize=18)
fig.subplots_adjust(left=.05,right=.97,top=.86,bottom=.08,wspace=.30)
_apply_bilingual_figure(plt.gcf(), _bfLabels, _bfOriginalPixels)
_display_bilingual_figure(plt.gcf())
assert pow(5,len(units),n)==1 and pow(5,2,n)==1
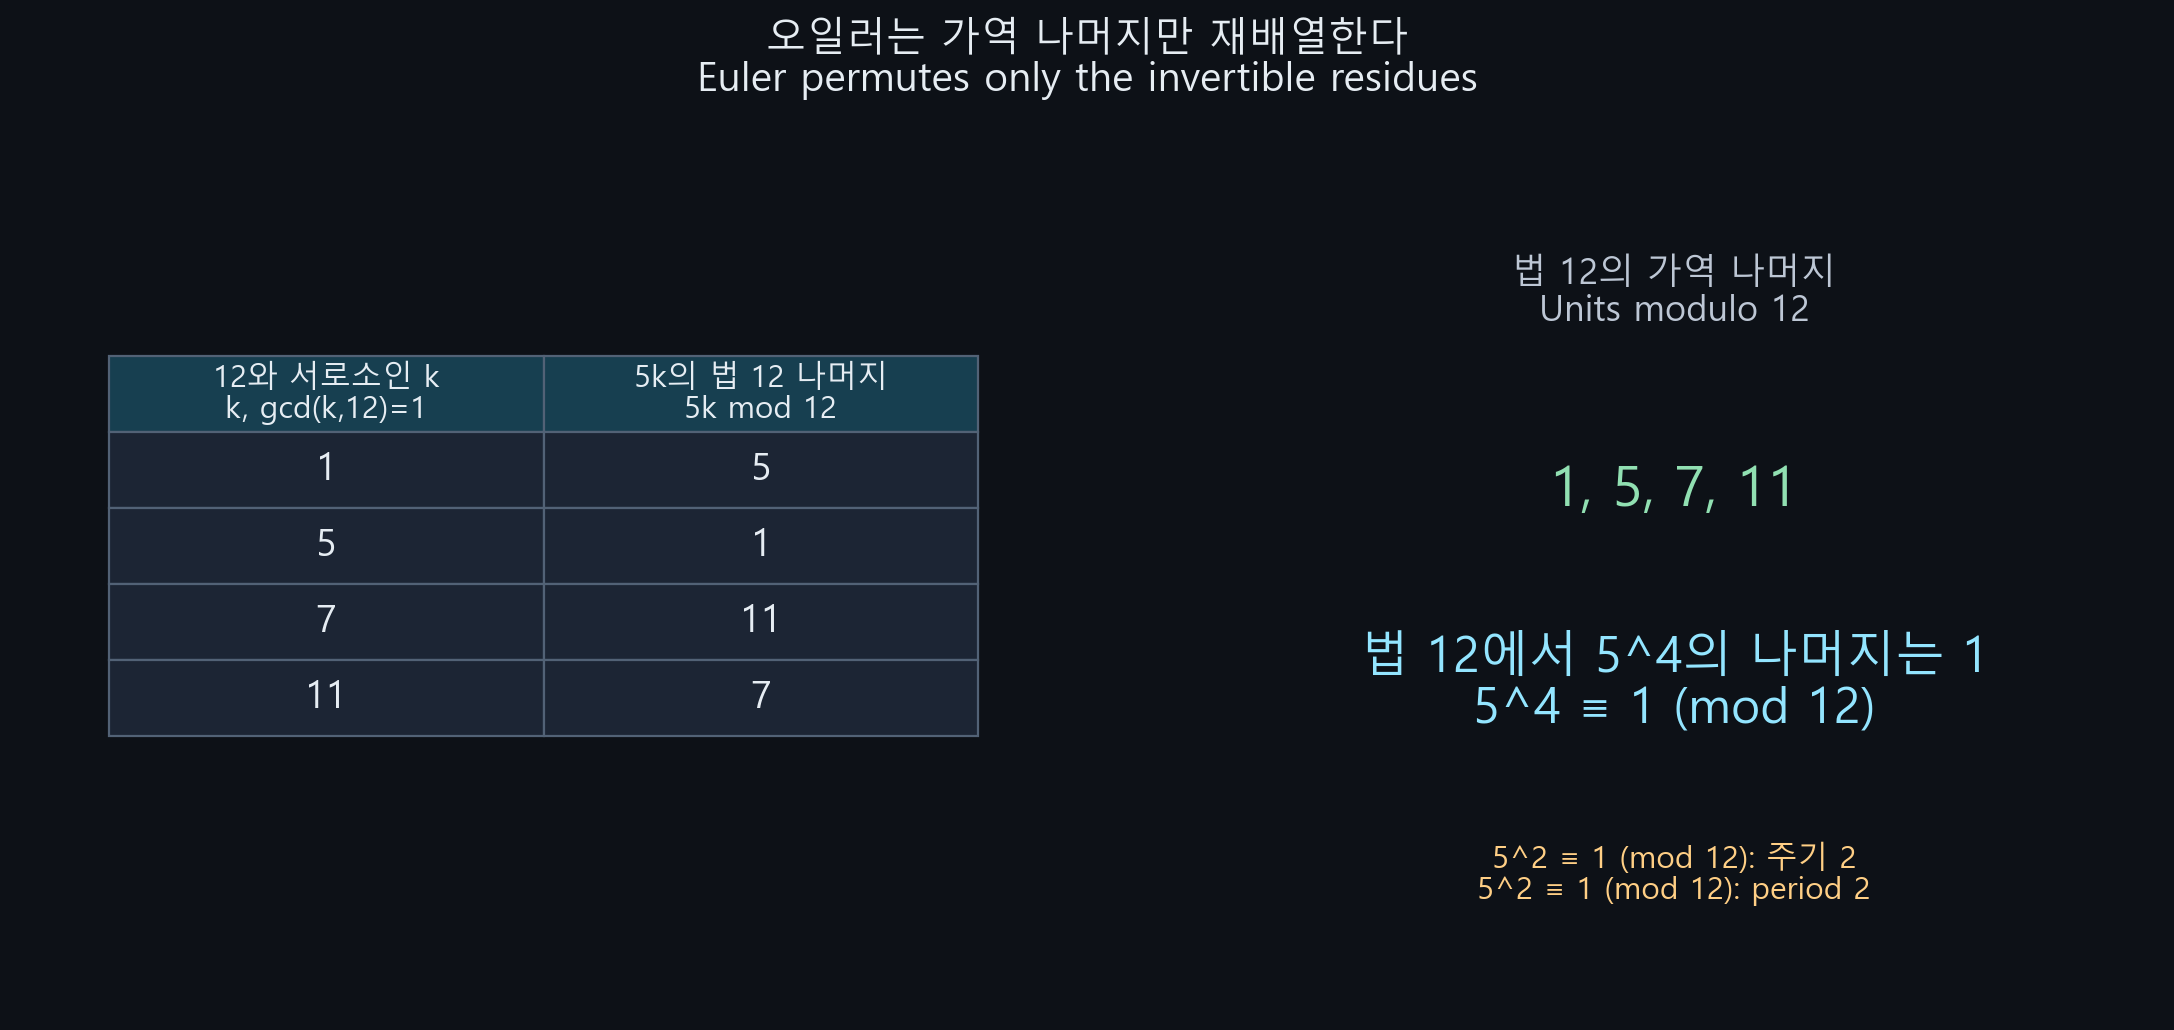
표에서는 네 수가 정말로 다시 나왔습니다. 이제 법과 곱하는 수를 바꾸어도 같은 일이 일어나는지 확인해보겠습니다. 일반적인 법 $n>1$에서 $n$과 서로소인 나머지를 $r_1,\ldots,r_h$라고 합시다. 작은 첨자는 목록의 첫째, 둘째처럼 자리를 가리킵니다. 개수 $h$가 바로 $\varphi(n)$입니다. 또한 $\gcd(a,n)=1$인 정수 $a$를 고릅니다. 앞의 표에서 12가 법, 1·5·7·11이 목록, 곱해 넣은 5가 마지막에 고른 수 $a$에 해당합니다.
먼저 $a$와 $r_i$의 곱 $ar_i$가 $n$과 서로소인 목록 밖으로 나가지 않는지 확인해야 합니다.
여기서 $a$와 $r_i$가 각각 $n$과 서로소라고 했으므로, 두 수를 곱한 $ar_i$도 $n$과 서로소입니다. 따라서 $ar_i$를 $n$으로 나눈 나머지도 우리가 처음 고른 목록에 속합니다.
좀 더 자세히 살펴보면 $a$와 $r_i$의 법 $n$에서의 역원을 함께 사용하면 $ar_i$도 1로 되돌릴 수 있습니다. $n$의 소인수가 $ar_i$를 나누려면 $a$나 $r_i$를 나누어야 한다는 성질로도 같은 결론을 얻습니다.
예를 들어 법 12에서 $a=5$, $r_i=7$을 곱하면 35이고, 나머지로 줄이면 11입니다. 5의 역원은 5, 7의 역원은 7이므로 $35\times(7\times5)=(5\times5)(7\times7)\equiv1\times1=1\pmod{12}$입니다. 곱한 결과도 다시 되돌릴 수 있습니다.
일반적으로 $a$의 역원을 $u$, $r_i$의 역원을 $v_i$라 쓰면
따라서 곱 $ar_i$에도 역원이 있고, 3편의 양방향 정리에 따라 $n$과 서로소입니다. $ar_i$를 작은 나머지 $s_i$로 바꾸어도 이 합동은 유지되므로 $s_i$ 역시 가역 목록 안에 있습니다.
다음으로 $ar_i\equiv ar_j\pmod n$이면 $a$의 역원을 곱해 $r_i\equiv r_j\pmod n$입니다. 대표들을 1부터 $n-1$ 사이에서 다르게 골랐으므로 $i=j$입니다. 따라서 서로 다른 입력의 출력이 충돌하지 않습니다.
출력은 모두 같은 가역 나머지 목록 안에 들어가고 서로 다르며, 개수도 그 목록의 개수 $h$와 같습니다. 그러므로 전체 목록이 재배열됩니다. 앞 편의 세 단계가 그대로 돌아왔습니다. 바뀐 것은 사용하는 목록이 영이 아닌 나머지 전체(페르마의 소정리)에서 서로소인 나머지 전체(오일러 정리)로 좁아졌다는 점입니다.
6. 오일러의 정리와 약분의 조건
목록이 유지된다는 사실까지 확인했습니다. 자, 이제 왜 이 수들을 모두 곱할까요? 각 항에 한 번씩 넣은 수를 한곳으로 모아 거듭제곱을 만들기 위해서입니다. 법 12의 표라면 네 항에 들어간 5가 모여 5의 네제곱이 됩니다. 동시에 곱한 뒤의 나머지는 원래 목록의 순서만 바꾼 것이므로, 전체 곱의 나머지는 전과 같습니다. 이 두 사실을 한 식에 담아보겠습니다.
왼쪽에 $a$가 $h$번 들어 있으므로 다음처럼 모을 수 있습니다. 양쪽에 남는 원래 목록의 긴 곱에는 이름 하나를 붙이겠습니다.
이제 $P$를 약분할 수 있을까요? 양변을 보통 정수처럼 무작정 나누는 대신, 법에서 곱을 1로 되돌리는 수가 있는지 확인해야 합니다. 각 $r_i$가 $n$과 서로소이므로 그 곱 $P$도 $n$과 서로소입니다. 따라서 $P$의 역원이 있고, 양변에 곱하여
을 얻습니다. 이것이 오일러의 정리입니다.
각 $r_i$의 역원이 $v_i$라면 $Q=v_1v_2\cdots v_h$라고 두어도 됩니다. 곱의 순서를 바꾸어 짝지으면 $PQ\equiv(r_1v_1)\cdots(r_hv_h)\equiv1$입니다. 따라서 $a^hP\equiv P$의 양쪽에 $Q$를 곱해 $a^h(PQ)\equiv PQ$, 곧 $a^h\equiv1$을 얻습니다. 약분하는 근거를 각 항의 역원에서 직접 구성한 것입니다.
법 12에서는 $h=4$이므로 $5^4\equiv1\pmod{12}$입니다. 실제로 $5^2=25\equiv1$이고, 그 제곱도 1입니다. 이처럼 정리가 주는 지수는 1이 되는 지수 하나이지 항상 최소 지수는 아닙니다.
소수 $p$에서는 $\varphi(p)=p-1$이므로 오일러의 정리는 페르마의 소정리를 그대로 포함합니다. 두 정리는 별개의 암기 항목이라기보다, 같은 증명에서 어떤 나머지를 목록에 올렸는가가 다른 경우입니다.
| 항목 | 소수 법 $p$ | 일반적인 법 $n$ |
|---|---|---|
| 사용할 목록 | 0 아닌 나머지 전체 | $n$과 서로소인 나머지 |
| 목록의 개수 | $p-1$ | $\varphi(n)$ |
| 곱하는 수의 조건 | $p\nmid a$ | $\gcd(a,n)=1$ |
| 얻는 합동식 | $a^{p-1}\equiv1$ | $a^{\varphi(n)}\equiv1$ |
서로소 조건을 빼면 어떻게 될까요? 법 12의 같은 목록에 6을 곱해보면, 네 결과가 모두 가역 목록(1, 5, 7, 11) 밖의 6으로 합쳐집니다.
아래 그림에서는 입력 $1,5,7,11$을 고정하고 5배와 6배의 목적지를 비교합니다.
그림을 만든 Python 코드
from pathlib import Path as _bfPath
from matplotlib.font_manager import FontProperties as _bfFontProperties
from matplotlib.text import Text as _bfText
from matplotlib.ticker import Formatter as _bfFormatter
from io import BytesIO as _bfBytesIO
from IPython.display import display as _bfDisplay, Image as _bfImage

class _BilingualFormatter(_bfFormatter):
    def __init__(self, base, labels):
        self.base, self.labels = base, labels
    def set_axis(self, axis):
        super().set_axis(axis)
        self.base.set_axis(axis)
    def set_locs(self, locs):
        super().set_locs(locs)
        self.base.set_locs(locs)
    def __call__(self, value, pos=None):
        raw=self.base(value,pos)
        translated=self.labels.get(raw)
        return translated+'\n'+raw if translated else raw
    def get_offset(self):
        return self.base.get_offset()

def _apply_bilingual_figure(_bfFigure, _bfLabels, _bfOriginalPixels):
    if getattr(_bfFigure, '_bilingual_complete', False):
        return
    _bfFont = _bfPath('C:/Windows/Fonts/malgun.ttf')
    if not _bfFont.is_file():
        raise RuntimeError('Korean/English figures require the Malgun Gothic font.')
    _bfFamily = _bfFontProperties(fname=str(_bfFont)).get_name()
    # Keep the delivered original's aspect ratio.  A bilingual label must not
    # stretch the chart, its grid cells, cards or geometry vertically.
    _bfFigure.set_size_inches(_bfOriginalPixels[0] / 80,
                             _bfOriginalPixels[1] / 80, forward=True)
    _bfFigure._bilingual_original_pixels = tuple(_bfOriginalPixels)
    _bfFigure.canvas.draw()
    for _bfAxes in _bfFigure.axes:
        for _bfAxis in (_bfAxes.xaxis,_bfAxes.yaxis):
            if any(_bfTick.get_text() in _bfLabels for _bfTick in _bfAxis.get_majorticklabels()):
                _bfAxis.set_major_formatter(_BilingualFormatter(_bfAxis.get_major_formatter(),_bfLabels))
    _bfTexts = list(_bfFigure.findobj(_bfText))
    for _bfAxes in _bfFigure.axes:
        for _bfTable in _bfAxes.tables:
            _bfTexts.extend(_bfCell.get_text() for _bfCell in _bfTable.get_celld().values())
    _bfSeen = set()
    _bfChanged = []
    for _bfItem in _bfTexts:
        if id(_bfItem) in _bfSeen:
            continue
        _bfSeen.add(id(_bfItem))
        _bfOriginal = _bfItem.get_text()
        _bfKorean = _bfLabels.get(_bfOriginal)
        if _bfKorean:
            _bfItem.set_text(_bfKorean + '\n' + _bfOriginal)
            _bfItem.set_linespacing(1.05)
            _bfChanged.append((_bfKorean, _bfOriginal))
        _bfProperties = _bfItem.get_fontproperties().copy()
        _bfProperties.set_file(None)
        _bfProperties.set_family([_bfFamily, 'DejaVu Sans'])
        _bfItem.set_fontproperties(_bfProperties)
    assert _bfChanged, 'Every figure must contain meaningful Korean/English labels.'
    # Bilingual column headers must stay inside their original table cells.
    _bfFigure.canvas.draw()
    _bfRenderer = _bfFigure.canvas.get_renderer()
    for _bfAxes in _bfFigure.axes:
        for _bfTable in _bfAxes.tables:
            for _bfCell in _bfTable.get_celld().values():
                _bfCellText = _bfCell.get_text()
                _bfBox = _bfCellText.get_window_extent(_bfRenderer)
                _bfCellBox = _bfCell.get_window_extent(_bfRenderer)
                if _bfBox.width and _bfBox.height:
                    _bfFit = min(1, .92*_bfCellBox.width/_bfBox.width,
                                  .88*_bfCellBox.height/_bfBox.height)
                    _bfCellText.set_fontsize(_bfCellText.get_fontsize()*_bfFit)
        if _bfAxes.get_title():
            _bfAxes.set_title(_bfAxes.get_title(), pad=6)
    _bfFigure.canvas.draw()
    # Keep subplot headings clear of the shared two-line title, moving the
    # subplot boundary only as much as the actual rendered text requires.
    if _bfFigure._suptitle is not None:
        _bfTopTitle = _bfFigure._suptitle.get_window_extent(_bfRenderer)
        for _bfAxes in _bfFigure.axes:
            if not _bfAxes.get_title():
                continue
            _bfHeading = _bfAxes.title.get_window_extent(_bfRenderer)
            _bfGap = _bfHeading.y1 - (_bfTopTitle.y0 - 9)
            if _bfGap > 0:
                _bfPosition = _bfAxes.get_position(original=True)
                _bfAxes.set_position([_bfPosition.x0, _bfPosition.y0,
                    _bfPosition.width, _bfPosition.height - _bfGap/_bfFigure.bbox.height])
    _bfFigure._bilingual_labels = _bfChanged
    _bfFigure._bilingual_complete = True

def _display_bilingual_figure(_bfFigure):
    # A fixed full canvas avoids notebook's automatic tight crop changing the
    # aspect ratio after titles and labels become bilingual.  This is a fresh
    # Matplotlib rendering, at exactly twice the original pixel dimensions.
    global _bfDisplayedFigure
    _bfDisplayedFigure = _bfFigure
    _bfBuffer = _bfBytesIO()
    _bfFigure.savefig(_bfBuffer, format='png', dpi=160, bbox_inches=None,
                      pad_inches=0, facecolor=_bfFigure.get_facecolor())
    _bfDisplay(_bfImage(data=_bfBuffer.getvalue()))
    plt.close(_bfFigure)

_bfLabels = {'Dividend': '피제수', 'Divisor': '제수', 'Quotient': '몫', 'Remainder': '나머지', '3r mod 7': '3r의 법 7 나머지', 'then x5': '그다음 5를 곱하기', 'k, gcd(k,12)=1': '12와 서로소인 k', '5k mod 12': '5k의 법 12 나머지', 'Modulus': '법', 'Other factors': '나머지 법들의 곱', 'Inverse': '역원', 'Unit part': '단위 부품', 'Target': '목표 나머지', 'Contribution': '기여값', 'Possible square residues': '가능한 제곱 나머지', 'Squares of 0, 1, ... , m-1': '0·1·…·(m−1)의 제곱 나머지', 'PASS': '통과', 'IMPOSSIBLE': '불가능', 'mod 2': '법 2', 'mod 3': '법 3', 'mod 4': '법 4', 'mod 5': '법 5', 'mod 7': '법 7', 'mod 8': '법 8', 'mod 9': '법 9', 'mod 11': '법 11', 'mod 12': '법 12', 'mod 105': '법 105', 'Multiply by 5 modulo 12': '법 12에서 5를 곱하기', 'gcd(5,12)=1\nOutputs are the same four units.': 'gcd(5,12)=1\n출력은 원래의 가역 나머지 네 개와 같다.', 'Multiply by 6 modulo 12': '법 12에서 6을 곱하기', 'gcd(6,12)=6\nAll four inputs collapse to the nonunit 6.': 'gcd(6,12)=6\n네 입력이 비가역 나머지 6으로 겹친다.', 'The coprime condition keeps the map inside the invertible residues': '서로소 조건이 있어야 가역 나머지 안에서 이동한다', "Euler's product argument needs both closure inside the unit set and the absence of collisions.": '오일러의 곱 비교에는 가역 집합 안의 닫힘과 충돌 없음이 모두 필요하다.'}
_bfOriginalPixels = [1271, 689]

from math import gcd, isqrt
import numpy as np
import matplotlib.pyplot as plt
from matplotlib.colors import ListedColormap
from matplotlib.patches import Rectangle, Circle, FancyBboxPatch, FancyArrowPatch

BG = "#101827"
PANEL = "#1d2b40"
INK = "#edf3fc"
MUTED = "#c0cede"
BLUE = "#8fdcff"
GREEN = "#91e0b2"
GOLD = "#ffd18c"
RED = "#ffaaaa"
LINE = "#667a96"

def canvas(rows=1, cols=1, size=(13.6, 6.8), title=""):
    fig, axes = plt.subplots(rows, cols, figsize=size, facecolor=BG,
                             squeeze=False)
    axes = axes.ravel().tolist()
    for ax in axes:
        ax.set_facecolor(BG)
        ax.tick_params(colors=INK, labelsize=12)
        for spine in ax.spines.values():
            spine.set_color(LINE)
    fig.suptitle(title, fontsize=18, color=INK, y=.98)
    fig.subplots_adjust(left=.07, right=.97, top=.86, bottom=.13,
                        wspace=.34, hspace=.48)
    return fig, axes

def off(ax):
    ax.set_xlim(0, 1)
    ax.set_ylim(0, 1)
    ax.axis("off")

def text(ax, x, y, value, color=INK, size=12, **kwargs):
    defaults = dict(ha="center", va="center", fontsize=size, color=color,
                    transform=ax.transAxes, linespacing=1.35)
    defaults.update(kwargs)
    return ax.text(x, y, value, **defaults)

def card(ax, x, y, width, height, value, edge=LINE, color=INK, size=14):
    ax.add_patch(FancyBboxPatch((x, y), width, height,
                 boxstyle="round,pad=0.012", transform=ax.transAxes,
                 facecolor=PANEL, edgecolor=edge, linewidth=1.4))
    text(ax, x+width/2, y+height/2, value, color=color, size=size)

def arrow(ax, start, end, color=BLUE):
    ax.add_patch(FancyArrowPatch(start, end, transform=ax.transAxes,
                 arrowstyle="-|>", mutation_scale=18,
                 color=color, linewidth=1.7))

def caption(fig, value):
    fig.text(.5, .035, value, ha="center", va="center",
             color=MUTED, fontsize=12)

fig,axes=canvas(1,2,size=(13.9,7.0),title="The coprime condition keeps the map inside the invertible residues")
units=[1,5,7,11]
for ax,factor in zip(axes,[5,6]):
    off(ax)
    outputs=sorted(set(factor*x%12 for x in units))
    text(ax,.5,.95,f"Multiply by {factor} modulo 12",color=BLUE,size=16)
    source_y={x:.78-i*.17 for i,x in enumerate(units)}
    target_y={value:.78-i*.17 for i,value in enumerate(outputs)}
    if factor==6:target_y={6:.52}
    for x,y in source_y.items():card(ax,.02,y-.045,.15,.09,str(x),size=14)
    for value,y in target_y.items():
        card(ax,.80,y-.045,.15,.09,str(value),edge=GREEN if factor==5 else RED,size=14)
    for x,y in source_y.items():
        arrow(ax,(.20,y),(.77,target_y[factor*x%12]),color=GREEN if factor==5 else GOLD)
    if factor==5:
        text(ax,.5,.08,"gcd(5,12)=1\nOutputs are the same four units.",color=GREEN,size=14)
    else:
        text(ax,.5,.08,"gcd(6,12)=6\nAll four inputs collapse to the nonunit 6.",color=GOLD,size=14)
caption(fig,"Euler's product argument needs both closure inside the unit set and the absence of collisions.")
assert sorted(5*x%12 for x in units)==units
assert {6*x%12 for x in units}=={6} and gcd(6,12)!=1
_apply_bilingual_figure(plt.gcf(), _bfLabels, _bfOriginalPixels)
_display_bilingual_figure(plt.gcf())
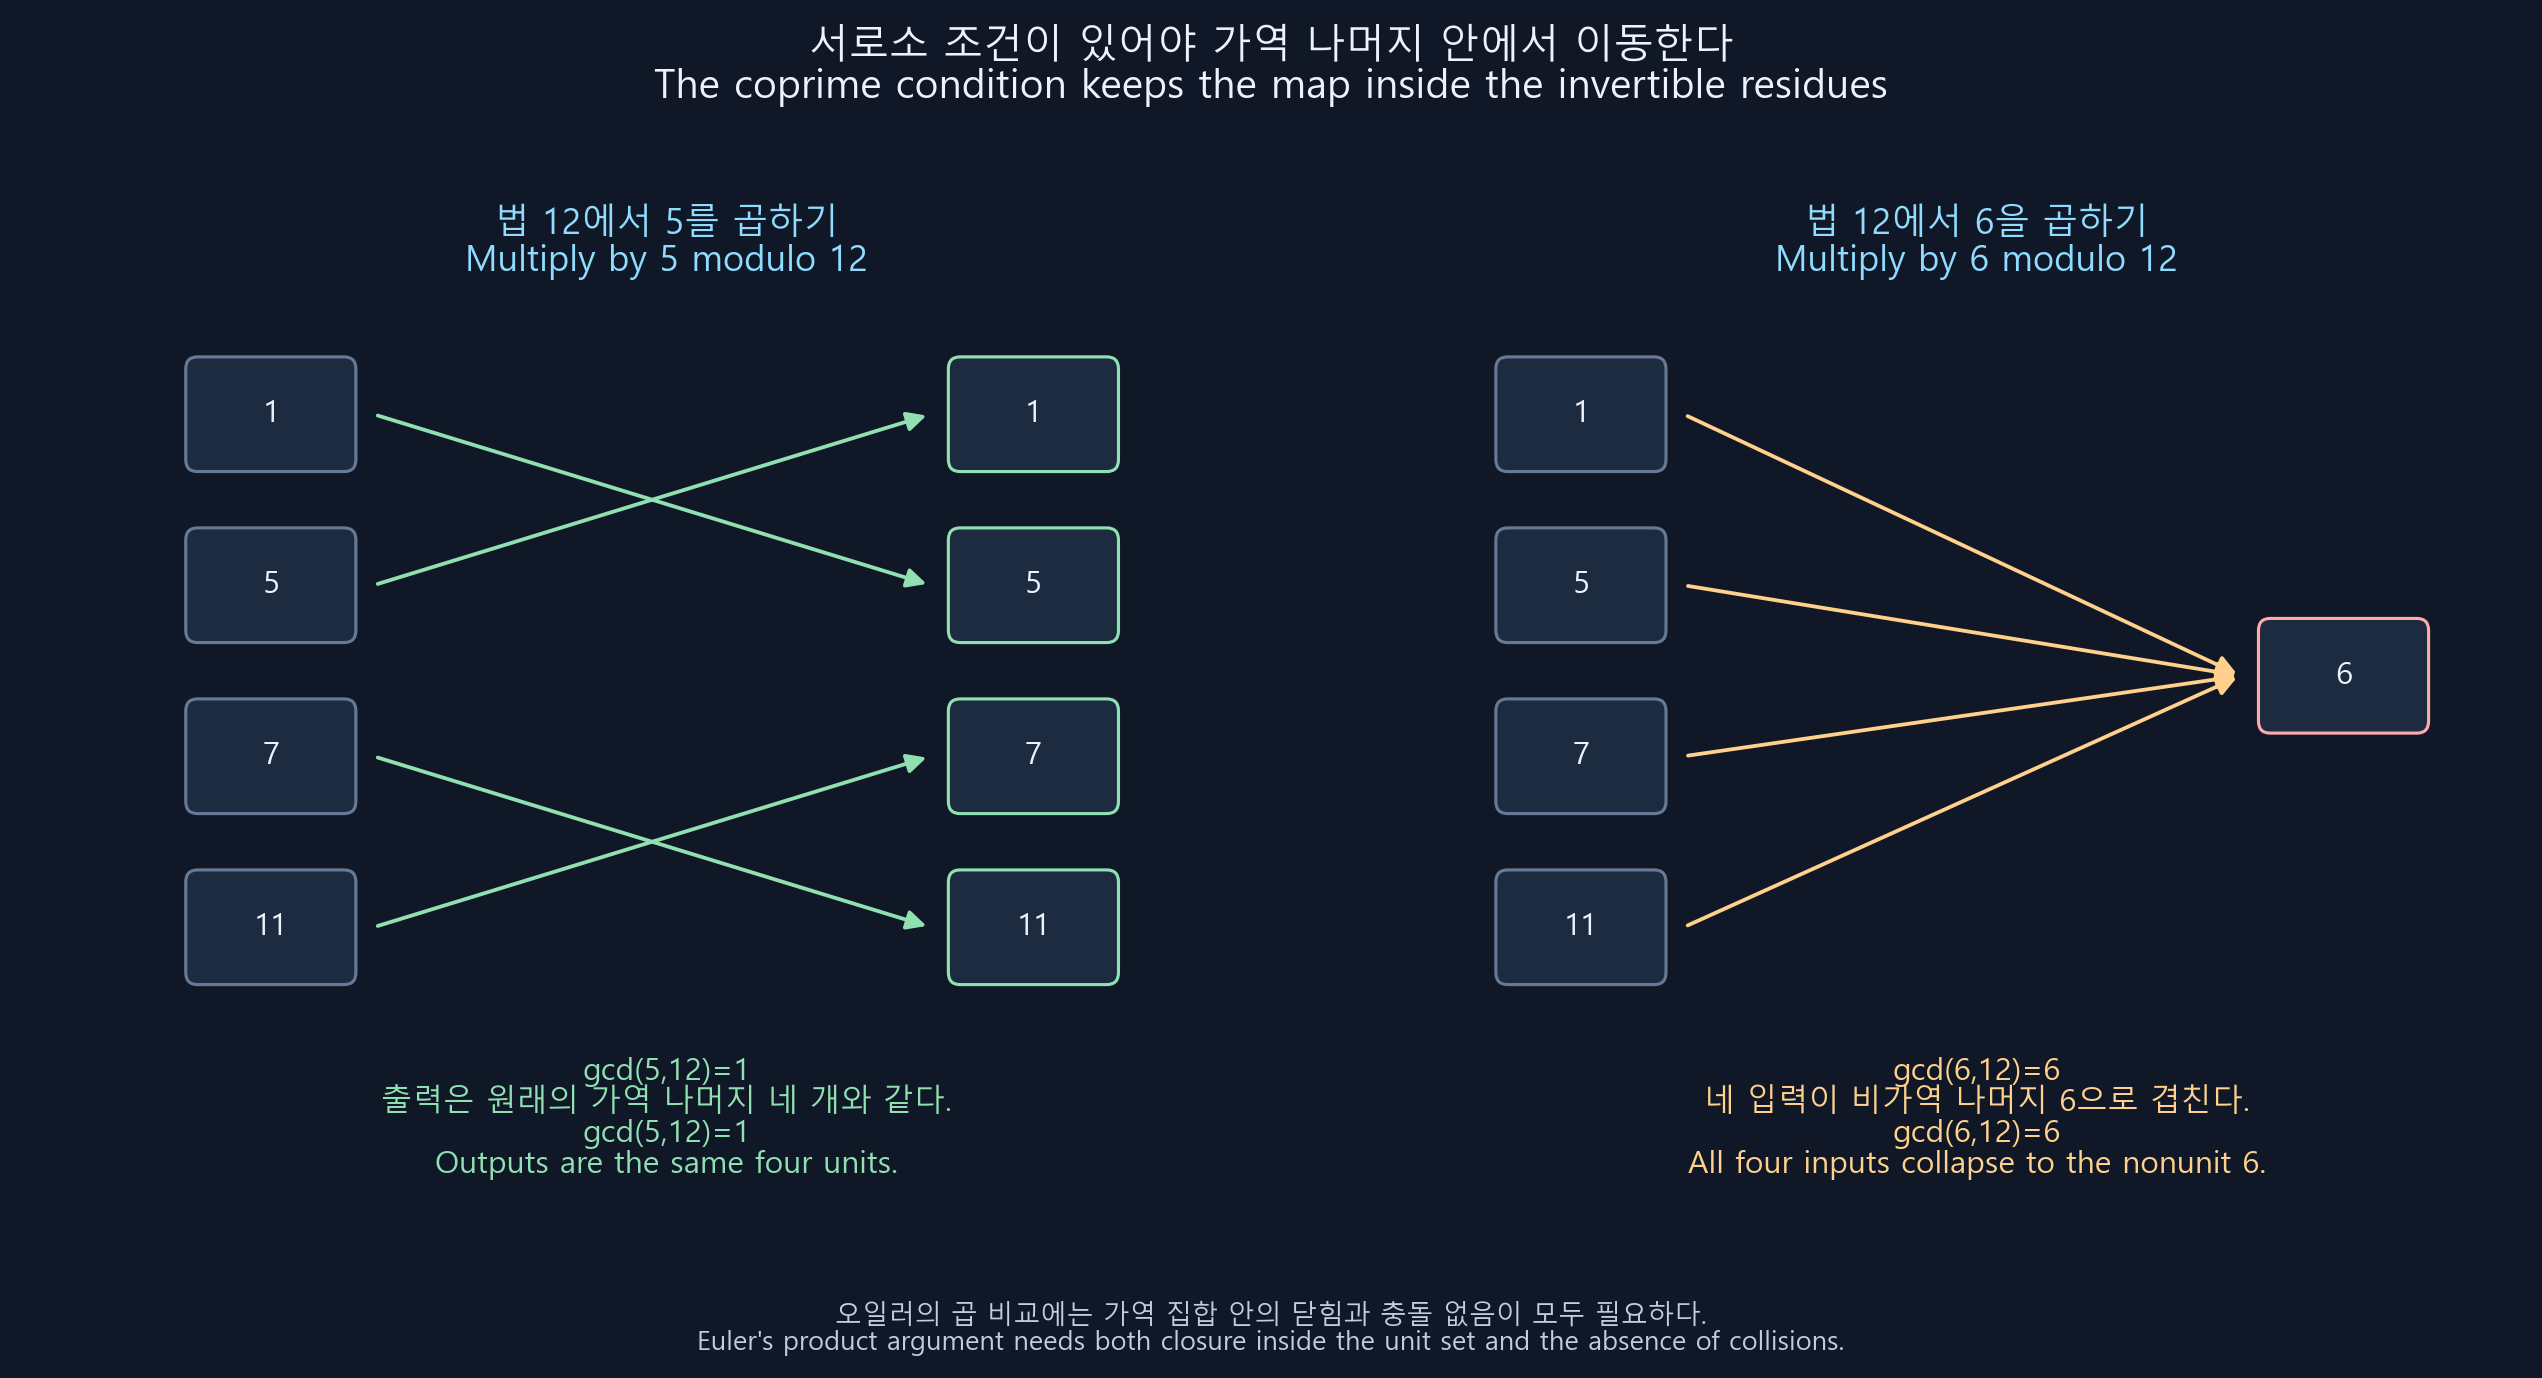
방금 본 법 12에서 6을 곱하는 예에서는 원래 목록 안에 머무른다는 성질과 충돌이 없다는 성질이 함께 무너집니다. 서로소 조건이 없을 때 이 두 성질을 모두 보장할 수 없다는 뜻이며, 모든 경우에 반드시 충돌까지 생긴다는 뜻은 아닙니다. 예를 들어 법 6의 가역 나머지 1과 5에 2를 곱하면 나머지는 각각 2와 4입니다. 두 출력은 서로 다르지만, 둘 다 원래 가역 목록 밖에 있습니다. 오일러의 정리는 목록을 고르는 조건과 곱하는 수의 조건을 모두 필요로 합니다.
7. 거듭제곱을 줄일 때 무엇을 먼저 확인할까요
$7^{100}$을 36으로 나눈 나머지를 구해봅시다. 7과 36은 서로소이고 $\varphi(36)=12$이므로
이제 7을 열두 번 곱한 덩어리마다 나머지를 1로 바꿀 수 있습니다. 백 번의 곱셈 속에 그런 덩어리가 몇 개 들어가고 몇 번이 남는지 세면 됩니다. $100=12\times8+4$로 나누면
남은 계산은 작습니다.
따라서 답은 25입니다. 원래 수를 만들지 않고 법 36의 작은 나머지들로 계산했습니다.
순서를 정리하면 법과 밑의 최대공약수를 확인하고, 피 함수를 구하고, 지수를 피 함수로 나눈 뒤, 남은 거듭제곱을 계산합니다.
첫 단계가 빠지면 틀릴 수 있습니다. 예를 들어 법 12에서 $\varphi(12)=4$라는 이유만으로 $2^4\equiv1$이라고 하면 안 됩니다.
정리가 적용되지 않는 경우에는 직접 나머지를 계산하거나 다른 구조를 살펴야 합니다. “지수를 $\varphi(n)$으로 나눈 나머지로 바꾼다”는 문장도 서로소 조건 아래에서만 안전합니다.
최소 주기와의 관계는 앞 편과 같습니다. $a^d\equiv1$을 만족하는 최소 양의 $d$를 위수라고 하면, 지수의 나눗셈으로 $d\mid\varphi(n)$임을 증명할 수 있습니다. $\varphi(n)=qd+r$라 두면 $a^{\varphi(n)}\equiv a^r\equiv1$이고 최소성 때문에 $r=0$이어야 합니다.
법 12에서 5의 위수는 2이고 $\varphi(12)=4$입니다. 법 36에서 7의 위수는 6이며 12를 나눕니다. 후자는 $7^3\equiv19$, $7^6\equiv19^2=361\equiv1$이고, 가능한 더 작은 약수 1·2·3에서는 1이 되지 않음을 확인하면 됩니다.
이때 후보가 왜 1·2·3뿐인지 한 단계를 덧붙이겠습니다. $7^6\equiv1$을 이미 확인했으므로 최소 위수 $d$는 6을 나눕니다. 앞 편에서 $a^h\equiv1$이면 $d\mid h$임을 증명했기 때문입니다. 따라서 후보는 6의 양의 약수 1·2·3·6뿐입니다. 실제로 $7^1\equiv7$, $7^2\equiv13$, $7^3\equiv19\pmod{36}$으로 앞의 세 후보가 탈락하므로 6이 남습니다. 12의 약수 4를 빠뜨린 것이 아니라, 더 강한 정보 $d\mid6$을 먼저 사용한 것입니다.
법 12의 5는 두 번 곱할 때 처음 1로 돌아오고, 법 36의 7은 여섯 번 곱할 때 처음 돌아옵니다. 그림의 막대는 각 밑의 최소 위수를, 점선은 해당 법의 피 함수 값을 나타냅니다.
그림을 만든 Python 코드
from pathlib import Path as _bfPath
from matplotlib.font_manager import FontProperties as _bfFontProperties
from matplotlib.text import Text as _bfText
from matplotlib.ticker import Formatter as _bfFormatter
from io import BytesIO as _bfBytesIO
from IPython.display import display as _bfDisplay, Image as _bfImage

class _BilingualFormatter(_bfFormatter):
    def __init__(self, base, labels):
        self.base, self.labels = base, labels
    def set_axis(self, axis):
        super().set_axis(axis)
        self.base.set_axis(axis)
    def set_locs(self, locs):
        super().set_locs(locs)
        self.base.set_locs(locs)
    def __call__(self, value, pos=None):
        raw=self.base(value,pos)
        translated=self.labels.get(raw)
        return translated+'\n'+raw if translated else raw
    def get_offset(self):
        return self.base.get_offset()

def _apply_bilingual_figure(_bfFigure, _bfLabels, _bfOriginalPixels):
    if getattr(_bfFigure, '_bilingual_complete', False):
        return
    _bfFont = _bfPath('C:/Windows/Fonts/malgun.ttf')
    if not _bfFont.is_file():
        raise RuntimeError('Korean/English figures require the Malgun Gothic font.')
    _bfFamily = _bfFontProperties(fname=str(_bfFont)).get_name()
    # Keep the delivered original's aspect ratio.  A bilingual label must not
    # stretch the chart, its grid cells, cards or geometry vertically.
    _bfFigure.set_size_inches(_bfOriginalPixels[0] / 80,
                             _bfOriginalPixels[1] / 80, forward=True)
    _bfFigure._bilingual_original_pixels = tuple(_bfOriginalPixels)
    _bfFigure.canvas.draw()
    for _bfAxes in _bfFigure.axes:
        for _bfAxis in (_bfAxes.xaxis,_bfAxes.yaxis):
            if any(_bfTick.get_text() in _bfLabels for _bfTick in _bfAxis.get_majorticklabels()):
                _bfAxis.set_major_formatter(_BilingualFormatter(_bfAxis.get_major_formatter(),_bfLabels))
    _bfTexts = list(_bfFigure.findobj(_bfText))
    for _bfAxes in _bfFigure.axes:
        for _bfTable in _bfAxes.tables:
            _bfTexts.extend(_bfCell.get_text() for _bfCell in _bfTable.get_celld().values())
    _bfSeen = set()
    _bfChanged = []
    for _bfItem in _bfTexts:
        if id(_bfItem) in _bfSeen:
            continue
        _bfSeen.add(id(_bfItem))
        _bfOriginal = _bfItem.get_text()
        _bfKorean = _bfLabels.get(_bfOriginal)
        if _bfKorean:
            _bfItem.set_text(_bfKorean + '\n' + _bfOriginal)
            _bfItem.set_linespacing(1.05)
            _bfChanged.append((_bfKorean, _bfOriginal))
        _bfProperties = _bfItem.get_fontproperties().copy()
        _bfProperties.set_file(None)
        _bfProperties.set_family([_bfFamily, 'DejaVu Sans'])
        _bfItem.set_fontproperties(_bfProperties)
    assert _bfChanged, 'Every figure must contain meaningful Korean/English labels.'
    # Bilingual column headers must stay inside their original table cells.
    _bfFigure.canvas.draw()
    _bfRenderer = _bfFigure.canvas.get_renderer()
    for _bfAxes in _bfFigure.axes:
        for _bfTable in _bfAxes.tables:
            for _bfCell in _bfTable.get_celld().values():
                _bfCellText = _bfCell.get_text()
                _bfBox = _bfCellText.get_window_extent(_bfRenderer)
                _bfCellBox = _bfCell.get_window_extent(_bfRenderer)
                if _bfBox.width and _bfBox.height:
                    _bfFit = min(1, .92*_bfCellBox.width/_bfBox.width,
                                  .88*_bfCellBox.height/_bfBox.height)
                    _bfCellText.set_fontsize(_bfCellText.get_fontsize()*_bfFit)
        if _bfAxes.get_title():
            _bfAxes.set_title(_bfAxes.get_title(), pad=6)
    _bfFigure.canvas.draw()
    # Keep subplot headings clear of the shared two-line title, moving the
    # subplot boundary only as much as the actual rendered text requires.
    if _bfFigure._suptitle is not None:
        _bfTopTitle = _bfFigure._suptitle.get_window_extent(_bfRenderer)
        for _bfAxes in _bfFigure.axes:
            if not _bfAxes.get_title():
                continue
            _bfHeading = _bfAxes.title.get_window_extent(_bfRenderer)
            _bfGap = _bfHeading.y1 - (_bfTopTitle.y0 - 9)
            if _bfGap > 0:
                _bfPosition = _bfAxes.get_position(original=True)
                _bfAxes.set_position([_bfPosition.x0, _bfPosition.y0,
                    _bfPosition.width, _bfPosition.height - _bfGap/_bfFigure.bbox.height])
    _bfFigure._bilingual_labels = _bfChanged
    _bfFigure._bilingual_complete = True

def _display_bilingual_figure(_bfFigure):
    # A fixed full canvas avoids notebook's automatic tight crop changing the
    # aspect ratio after titles and labels become bilingual.  This is a fresh
    # Matplotlib rendering, at exactly twice the original pixel dimensions.
    global _bfDisplayedFigure
    _bfDisplayedFigure = _bfFigure
    _bfBuffer = _bfBytesIO()
    _bfFigure.savefig(_bfBuffer, format='png', dpi=160, bbox_inches=None,
                      pad_inches=0, facecolor=_bfFigure.get_facecolor())
    _bfDisplay(_bfImage(data=_bfBuffer.getvalue()))
    plt.close(_bfFigure)

_bfLabels = {'Dividend': '피제수', 'Divisor': '제수', 'Quotient': '몫', 'Remainder': '나머지', '3r mod 7': '3r의 법 7 나머지', 'then x5': '그다음 5를 곱하기', 'k, gcd(k,12)=1': '12와 서로소인 k', '5k mod 12': '5k의 법 12 나머지', 'Modulus': '법', 'Other factors': '나머지 법들의 곱', 'Inverse': '역원', 'Unit part': '단위 부품', 'Target': '목표 나머지', 'Contribution': '기여값', 'Possible square residues': '가능한 제곱 나머지', 'Squares of 0, 1, ... , m-1': '0·1·…·(m−1)의 제곱 나머지', 'PASS': '통과', 'IMPOSSIBLE': '불가능', 'mod 2': '법 2', 'mod 3': '법 3', 'mod 4': '법 4', 'mod 5': '법 5', 'mod 7': '법 7', 'mod 8': '법 8', 'mod 9': '법 9', 'mod 11': '법 11', 'mod 12': '법 12', 'mod 105': '법 105', 'order 1': '최소 주기 1', 'order 2': '최소 주기 2', 'Euler exponent: 4': '오일러의 지수: 4', 'Coprime base a': '법과 서로소인 밑 a', 'Positive exponent': '양의 지수', 'Modulo 12': '법 12', 'order 6': '최소 주기 6', 'order 3': '최소 주기 3', 'Euler exponent: 12': '오일러의 지수: 12', 'Modulo 36': '법 36', 'Euler gives a shared exponent; different bases can return earlier': '오일러는 공통 지수를 보장하며, 밑에 따라 더 일찍 돌아올 수 있다', 'Every displayed minimum divides the guaranteed exponent.  Equality is not required.': '표시된 최소 주기는 모두 보장 지수의 약수이다. 같을 필요는 없다.'}
_bfOriginalPixels = [1302, 679]

from math import gcd, isqrt
import numpy as np
import matplotlib.pyplot as plt
from matplotlib.colors import ListedColormap
from matplotlib.patches import Rectangle, Circle, FancyBboxPatch, FancyArrowPatch

BG = "#101827"
PANEL = "#1d2b40"
INK = "#edf3fc"
MUTED = "#c0cede"
BLUE = "#8fdcff"
GREEN = "#91e0b2"
GOLD = "#ffd18c"
RED = "#ffaaaa"
LINE = "#667a96"

def canvas(rows=1, cols=1, size=(13.6, 6.8), title=""):
    fig, axes = plt.subplots(rows, cols, figsize=size, facecolor=BG,
                             squeeze=False)
    axes = axes.ravel().tolist()
    for ax in axes:
        ax.set_facecolor(BG)
        ax.tick_params(colors=INK, labelsize=12)
        for spine in ax.spines.values():
            spine.set_color(LINE)
    fig.suptitle(title, fontsize=18, color=INK, y=.98)
    fig.subplots_adjust(left=.07, right=.97, top=.86, bottom=.13,
                        wspace=.34, hspace=.48)
    return fig, axes

def off(ax):
    ax.set_xlim(0, 1)
    ax.set_ylim(0, 1)
    ax.axis("off")

def text(ax, x, y, value, color=INK, size=12, **kwargs):
    defaults = dict(ha="center", va="center", fontsize=size, color=color,
                    transform=ax.transAxes, linespacing=1.35)
    defaults.update(kwargs)
    return ax.text(x, y, value, **defaults)

def card(ax, x, y, width, height, value, edge=LINE, color=INK, size=14):
    ax.add_patch(FancyBboxPatch((x, y), width, height,
                 boxstyle="round,pad=0.012", transform=ax.transAxes,
                 facecolor=PANEL, edgecolor=edge, linewidth=1.4))
    text(ax, x+width/2, y+height/2, value, color=color, size=size)

def arrow(ax, start, end, color=BLUE):
    ax.add_patch(FancyArrowPatch(start, end, transform=ax.transAxes,
                 arrowstyle="-|>", mutation_scale=18,
                 color=color, linewidth=1.7))

def caption(fig, value):
    fig.text(.5, .035, value, ha="center", va="center",
             color=MUTED, fontsize=12)

def order(a,n):
    if gcd(a,n)!=1:raise ValueError("The base must be coprime to the modulus.")
    value=1
    for k in range(1,n+1):
        value=value*a%n
        if value==1:return k
    raise AssertionError("A unit has finite order.")

fig,axes=canvas(1,2,size=(13.8,6.9),title="Euler gives a shared exponent; different bases can return earlier")
for ax,n,bases,phi in [(axes[0],12,[1,5,7,11],4),(axes[1],36,[5,7,13,17],12)]:
    actual=[order(a,n) for a in bases]
    ax.bar(range(len(bases)),actual,color=BLUE,width=.58)
    ax.axhline(phi,color=GOLD,linestyle="--",linewidth=2)
    for j,d in enumerate(actual):
        ax.text(j,d+.25,f"order {d}",ha="center",color=INK,fontsize=12)
    ax.text(1.5,phi+.6,f"Euler exponent: {phi}",ha="center",color=GOLD,fontsize=14)
    ax.set_xticks(range(len(bases)),[str(a) for a in bases])
    ax.set_xlabel("Coprime base a",color=INK,fontsize=12)
    ax.set_ylabel("Positive exponent",color=INK,fontsize=12)
    ax.set_ylim(0,phi+3)
    ax.set_title(f"Modulo {n}",color=INK,fontsize=16,pad=15)
    ax.grid(axis="y",alpha=.18,color=LINE)
    assert all(phi%d==0 and pow(a,phi,n)==1 for a,d in zip(bases,actual))
caption(fig,"Every displayed minimum divides the guaranteed exponent.  Equality is not required.")
assert order(5,12)==2 and order(7,36)==6
fig.subplots_adjust(bottom=.19)
_apply_bilingual_figure(plt.gcf(), _bfLabels, _bfOriginalPixels)
_display_bilingual_figure(plt.gcf())
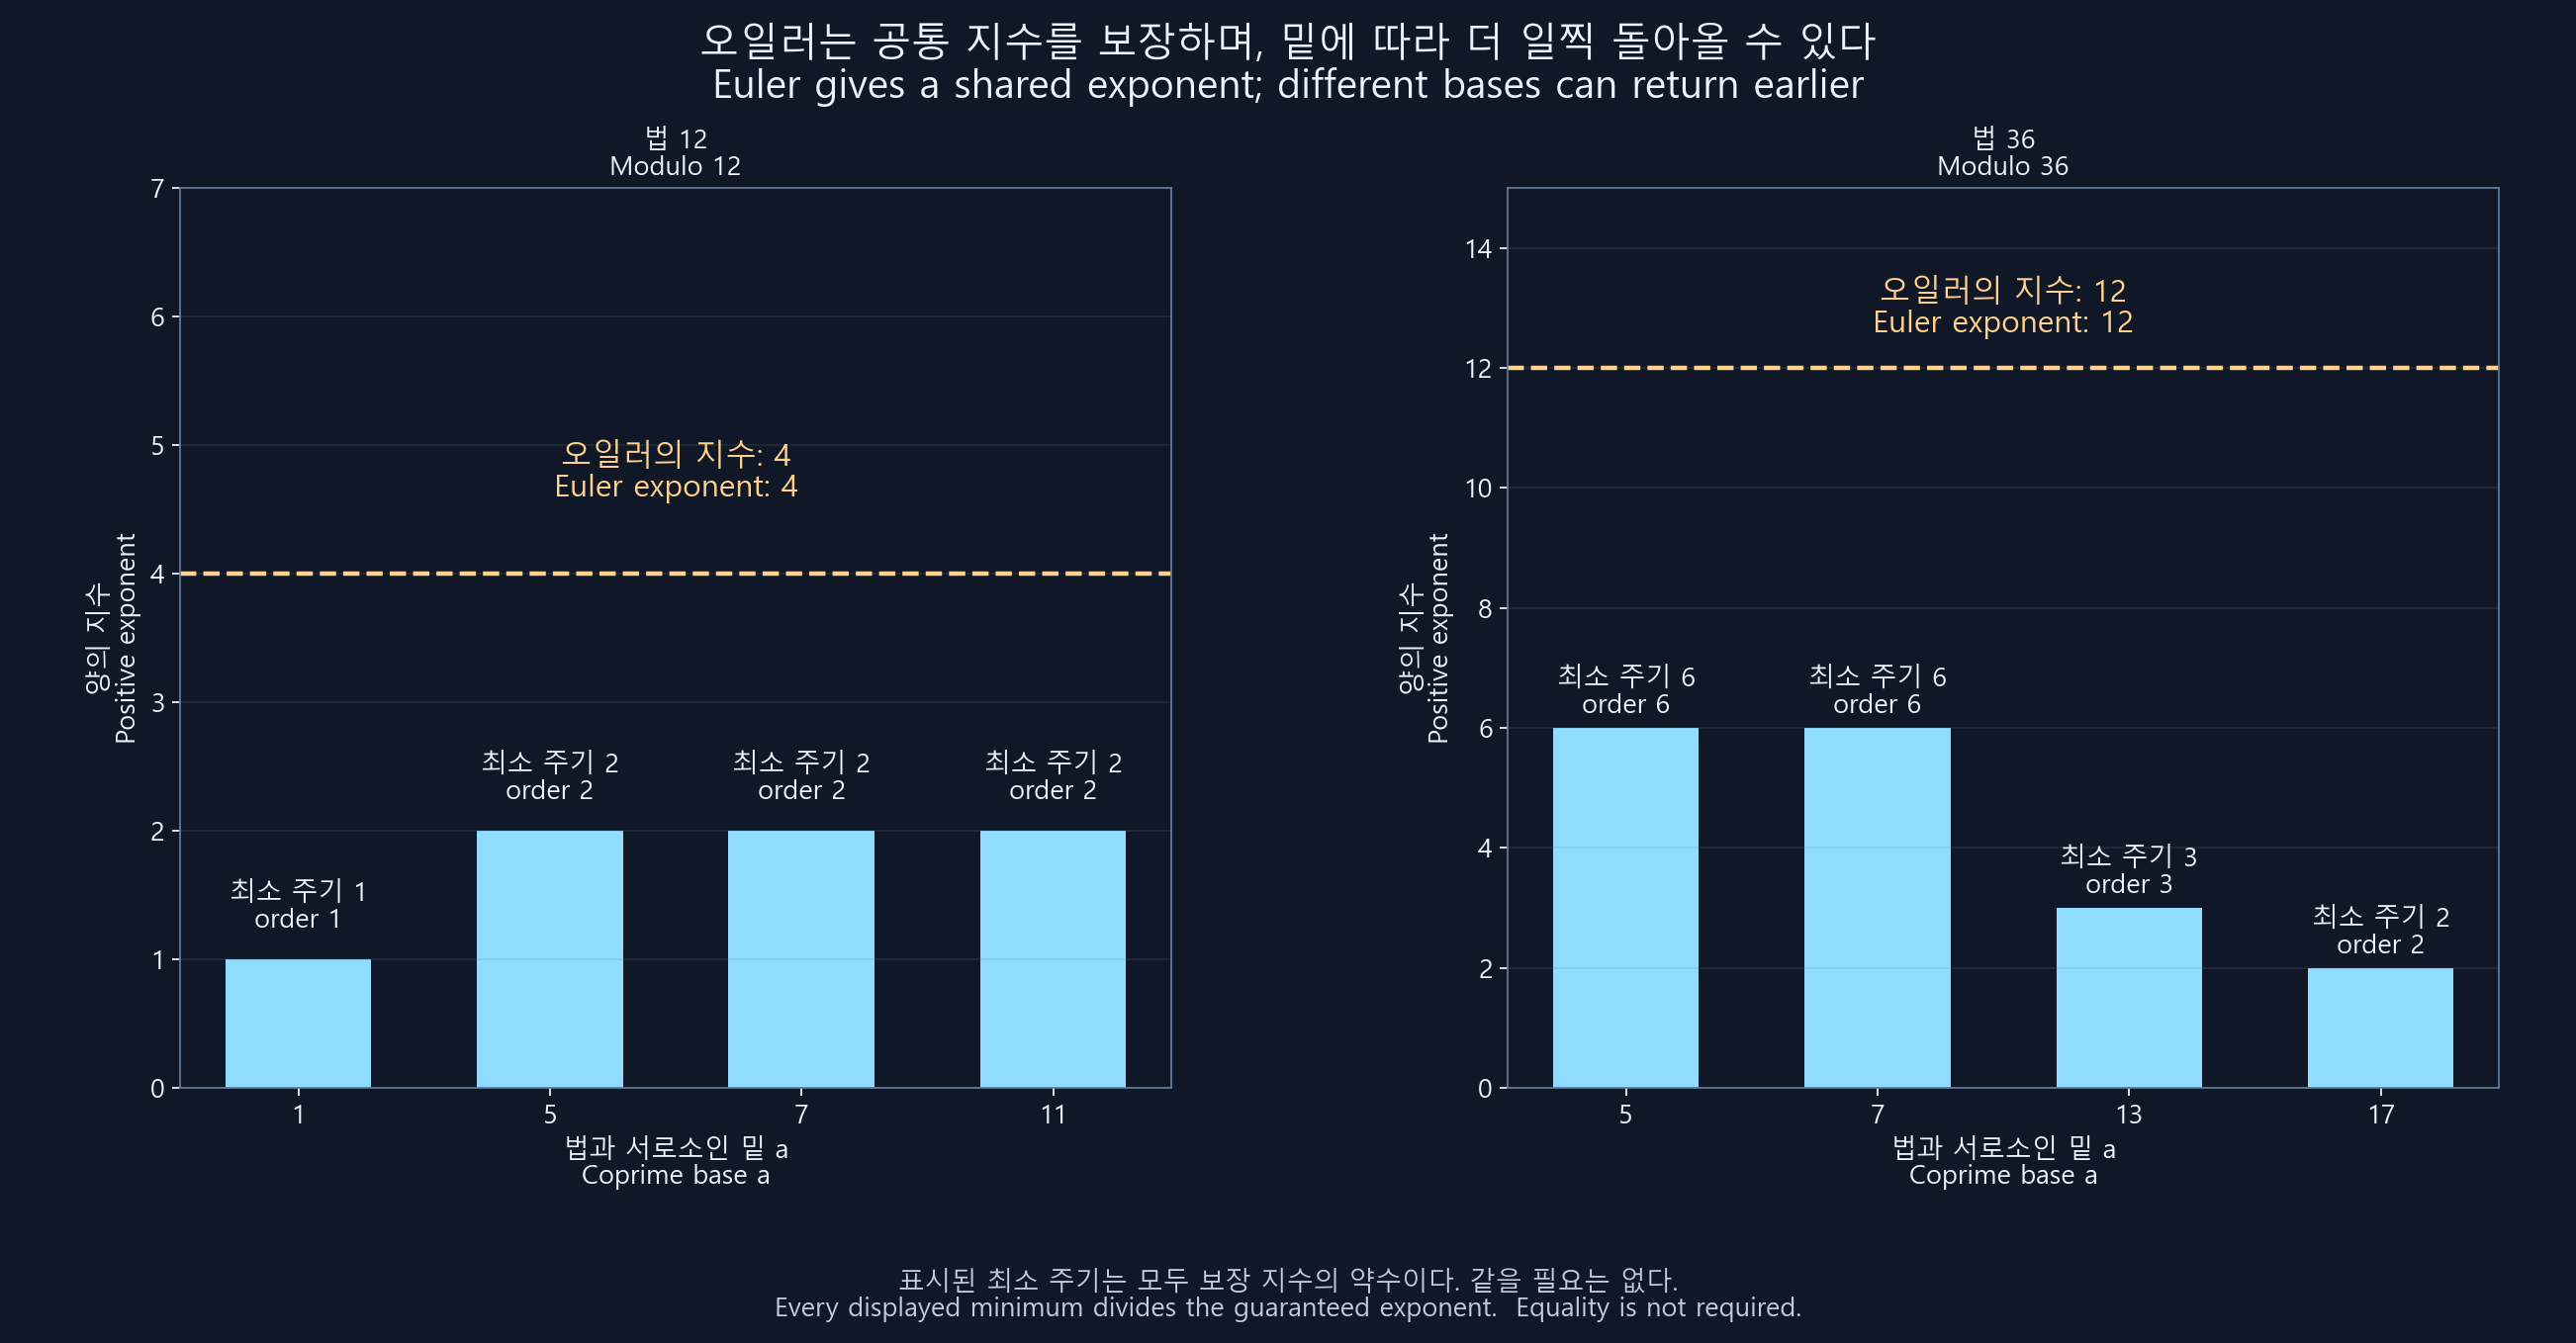
같은 법에서도 밑에 따라 최소 위수는 달라지지만, 각 막대의 높이는 그 법의 피 함수 값을 나눕니다. 보장 지수와 최소 지수를 구별하되 둘을 연결하는 나눗셈 관계도 함께 읽으면 됩니다.
8. 세기에서 얻은 곱 공식이 알려주는 것
앞에서 36과 서로소인 수를 12개라고 셌지요. 36을 서로소인 두 수 4와 9의 곱으로 나누어 놓고, 각각 센 개수를 곱해도 같은 답을 얻을 수 있을까요? 피 함수의 공식으로 그 이유를 확인해보겠습니다. 서로소인 양의 정수 $m,n$은 공통 소인수가 없어서, 두 소인수 목록이 서로 겹치지 않습니다. 따라서 $mn$의 서로 다른 소인수는 두 집합을 합친 것이고
예를 들어 4와 9는 서로소이고 $\varphi(4)=2$, $\varphi(9)=6$이므로 $\varphi(36)=12$입니다. 이미 직접 센 값과 일치합니다.
공통인수가 있으면 이 식을 그대로 쓰면 안 됩니다. $\varphi(4)\varphi(6)=2\times2=4$이지만 $\varphi(24)=8$입니다. 4와 6에 공통인수 2가 있어서 서로 다른 소인수 목록을 단순히 분리할 수 없기 때문입니다. 양쪽의 피 함수를 각각 계산해 곱하면, 2의 배수를 지우는 비율이 두 번 들어갑니다. 반면 24에서 서로소인 수를 셀 때에는 2의 배수를 한 번만 지워야 합니다. 이 차이가 서로소 조건이 필요한 자리입니다.
다음 편에서는 서로소인 두 법의 나머지 조건을 한 정수로 조합하겠습니다. 오늘은 포함배제로 센 개수를, 그때에는 가능한 나머지 쌍의 개수로 다시 세어볼 수 있습니다.
9. 직접 바꾸어 확인해보기
12·30·36을 차례로 입력해 직접 센 개수와 소인수 곱 공식이 일치하는지 확인해보세요. 36에 2와 3이 반복해서 들어 있어도 서로 다른 소인수는 두 종류라는 점을 살펴봅니다.
서로소인 수 세기
1부터 n까지 직접 세고, 서로 다른 소인수로 계산한 결과와 비교합니다.
이제 개수를 세는 실험에서 거듭제곱의 반복으로 넘어가봅시다. 법 12에서는 밑을 5로, 법 36에서는 7로 두어 피 함수와 처음 1로 돌아오는 지수를 비교해보세요.
오일러의 보장과 첫 반복
φ(n)이 보장하는 지수와 실제로 처음 1이 되는 지수를 따로 찾습니다.
같은 법에서도 밑에 따라 위수가 달라질 수 있지만, 서로소인 경우에는 피 함수의 약수입니다. 밑을 법과 서로소가 아닌 수로 바꾸었을 때는 그 조건이 성립하지 않음을 먼저 확인해야 합니다.
10. 마무리
오일러 피 함수는 이름이 붙은 복잡한 함수이기 전에, 법과 서로소인 수가 몇 개인지를 세는 함수입니다. 12에서는 2와 3의 배수를 지우고 겹친 것을 되돌려 네 수를 남겼습니다. 30에서는 세 겹의 중복까지 보정했고, 그 계산을 인수분해하여 일반 곱 공식을 얻었습니다.
남은 나머지들에는 역원이 있습니다. 서로소인 수를 곱해도 같은 목록 안에서 중복 없이 재배열되므로, 전체 곱을 비교하고 취소하면 오일러의 정리가 나옵니다. 세기와 거듭제곱이 연결되는 지점입니다.
이제 나머지 하나를 다루는 도구는 제법 갖추었습니다. 다음 편에서는 “3으로 나누면 2, 5로 나누면 3, 7로 나누면 2”라는 여러 조건을 한 정수로 합쳐보겠습니다. 그때 오늘의 서로소성은 조건들을 충돌 없이 연결하는 데 쓰입니다.